Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 260 results for "Curtis W Marean" clear search
COVID-19 SIR with Public Health Interventions
Kit Martin Amber Cesare Matthew Johnson | Published Tuesday, September 28, 2021This is an extension of the basic Suceptible, Infected, Recovered (SIR) model. This model explores the spread of disease in two spaces, one a treatment, and one a control. Through the modeling options, one can explore how changing assumptions about the number of susceptible people, starting number of infected people, the disease’s infection probability, and average duration impacts the outcome. In addition, this version allows users to explore how public health interventions like social distancing, masking, and isolation can affect the number of people infected. The model shows that the interactions of agents, and the interventions can drastically affect the results of the model.
We used the model in our course about COVID-19: https://www.csats.psu.edu/science-of-covid19
Modelling Academics as Agents: An Implementation of an Agent-Based Strategic Publication Model
Keith Nesbitt Xin Gu David Cornforth Karen Blackmore | Published Wednesday, July 23, 2014 | Last modified Wednesday, July 13, 2022The purpose of this agent-based model is to explore the emergent phenomena associated with scientific publication, including quantity and quality, from different academic types based on their publication strategies.
Livestock drought insurance model
Birgit Müller Felix John Jürgen Groeneveld Karin Frank Russell Toth | Published Tuesday, December 19, 2017 | Last modified Saturday, April 14, 2018The model analyzes the economic and ecological effects of a provision of livestock drought insurance for dryland pastoralists. More precisely, it yields qualitative insights into how long-term herd and pasture dynamics change through insurance.
This model extends the original Artifical Anasazi (AA) model to include individual agents, who vary in age and sex, and are aggregated into households. This allows more realistic simulations of population dynamics within the Long House Valley of Arizona from AD 800 to 1350 than are possible in the original model. The parts of this model that are directly derived from the AA model are based on Janssen’s 1999 Netlogo implementation of the model; the code for all extensions and adaptations in the model described here (the Artificial Long House Valley (ALHV) model) have been written by the authors. The AA model included only ideal and homogeneous “individuals” who do not participate in the population processes (e.g., birth and death)–these processes were assumed to act on entire households only. The ALHV model incorporates actual individual agents and all demographic processes affect these individuals. Individuals are aggregated into households that participate in annual agricultural and demographic cycles. Thus, the ALHV model is a combination of individual processes (birth and death) and household-level processes (e.g., finding suitable agriculture plots).
As is the case for the AA model, the ALHV model makes use of detailed archaeological and paleoenvironmental data from the Long House Valley and the adjacent areas in Arizona. It also uses the same methods as the original model (from Janssen’s Netlogo implementation) to estimate annual maize productivity of various agricultural zones within the valley. These estimates are used to determine suitable locations for households and farms during each year of the simulation.
Can ethnic tolerance curb self-reinforcing school segregation? A theoretical Agent Based Model
Lucas Sage Andreas Flache | Published Monday, August 10, 2020Schelling and Sakoda prominently proposed computational models suggesting that strong ethnic residential segregation can be the unintended outcome of a self-reinforcing dynamic driven by choices of individuals with rather tolerant ethnic preferences. There are only few attempts to apply this view to school choice, another important arena in which ethnic segregation occurs. In the current paper, we explore with an agent-based theoretical model similar to those proposed for residential segregation, how ethnic tolerance among parents can affect the level of school segregation. More specifically, we ask whether and under which conditions school segregation could be reduced if more parents hold tolerant ethnic preferences. We move beyond earlier models of school segregation in three ways. First, we model individual school choices using a random utility discrete choice approach. Second, we vary the pattern of ethnic segregation in the residential context of school choices systematically, comparing residential maps in which segregation is unrelated to parents’ level of tolerance to residential maps reflecting their ethnic preferences. Third, we introduce heterogeneity in tolerance levels among parents belonging to the same group. Our simulation experiments suggest that ethnic school segregation can be a very robust phenomenon, occurring even when about half of the population prefers mixed to segregated schools. However, we also identify a “sweet spot” in the parameter space in which a larger proportion of tolerant parents makes the biggest difference. This is the case when parents have moderate preferences for nearby schools and there is only little residential segregation. Further experiments are presented that unravel the underlying mechanisms.
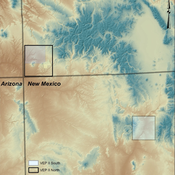
Village Ecodynamics Project
ipem | Published Friday, May 13, 2011 | Last modified Saturday, April 27, 2013The Village Project is designed to help archaeologists understand the factors influencing settlement patterns of small-scale agrarian peoples. Although such societies are becoming increasingly rare, they represent the norm throughout most of the Neolithic period the world over.
Peer reviewed An extended replication of Abelson's and Bernstein's community referendum simulation
Klaus G. Troitzsch | Published Friday, October 25, 2019 | Last modified Friday, August 25, 2023This is an extended replication of Abelson’s and Bernstein’s early computer simulation model of community referendum controversies which was originally published in 1963 and often cited, but seldom analysed in detail. This replication is in NetLogo 6.3.0, accompanied with an ODD+D protocol and class and sequence diagrams.
This replication replaces the original scales for attitude position and interest in the referendum issue which were distributed between 0 and 1 with values that are initialised according to a normal distribution with mean 0 and variance 1 to make simulation results easier compatible with scales derived from empirical data collected in surveys such as the European Value Study which often are derived via factor analysis or principal component analysis from the answers to sets of questions.
Another difference is that this model is not only run for Abelson’s and Bernstein’s ten week referendum campaign but for an arbitrary time in order that one can find out whether the distributions of attitude position and interest in the (still one-dimensional) issue stabilise in the long run.
Peer reviewed HUMLAND: HUMan impact on LANDscapes agent-based model
Fulco Scherjon Anastasia Nikulina Anhelina Zapolska Maria Antonia Serge Marco Davoli Dave van Wees Katharine MacDonald | Published Monday, October 16, 2023The HUMan impact on LANDscapes (HUMLAND) model has been developed to track and quantify the intensity of different impacts on landscapes at the continental level. This agent-based model focuses on determining the most influential factors in the transformation of interglacial vegetation with a specific emphasis on burning organized by hunter-gatherers. HUMLAND integrates various spatial datasets as input and target for the agent-based model results. Additionally, the simulation incorporates recently obtained continental-scale estimations of fire return intervals and the speed of vegetation regrowth. The obtained results include maps of possible scenarios of modified landscapes in the past and quantification of the impact of each agent, including climate, humans, megafauna, and natural fires.
Bicycle model
Gudrun Wallentin Dana Kaziyeva Martin Loidl | Published Thursday, January 10, 2019 | Last modified Monday, February 22, 2021The purpose of the model is to generate the spatio-temporal distribution of bicycle traffic flows at a regional scale level. Disaggregated results are computed for each network segment with the minute time step. The human decision-making is governed by probabilistic rules derived from the mobility survey.
Geospatial Agent-Based Model of Immigrant Settlement Dynamics in Metro Vancouver
Liliana Perez Navid Mahdizadeh Gharakhanlou Maryam Yousefi | Published Wednesday, December 03, 2025This agent-based model simulates how new immigrant households choose where to live in Metro Vancouver under the origins diversity scenario. The model begins with 16,000 household agents, reflecting an expected annual population increase of about 42,500 people based on an average household size of 2.56. Each agent is assigned four characteristics: one of ten origin categories, income level (adjusted using NOC data and recent immigrant earnings), likelihood of having children, and preferred mode of commuting. The ten origin groups are drawn from Census patterns, including six subgroups within the broader Asian category (China, India, the Philippines, Iran, South Korea, and Other Asian countries) and two categories for immigrants from the Americas. This refined classification better captures the diversity of newcomers arriving in the region.
Displaying 10 of 260 results for "Curtis W Marean" clear search