Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 204 results for "Kasper H Kisjes" clear search
Linear Threshold
Kaushik Sarkar | Published Saturday, November 03, 2012 | Last modified Saturday, April 27, 2013NetLogo implementation of Linear Threshold model of influence propagation.
Peer reviewed Descriptive Norm and Fraud Dynamics
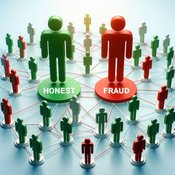
Alexandra Eckert Matthias Meyer Christian Stindt | Published Tuesday, January 07, 2025 | Last modified Tuesday, March 24, 2026The “Descriptive Norm and Fraud Dynamics” model demonstrates how fraudulent behavior can either proliferate or be contained within non-hierarchical organizations, such as peer networks, through social influence taking the form of a descriptive norm. This model expands on the fraud triangle theory, which posits that an individual must concurrently possess a financial motive, perceive an opportunity, and hold a pro-fraud attitude to engage in fraudulent activities (red agent). In the absence of any of these elements, the individual will act honestly (green agent).
The model explores variations in a descriptive norm mechanism, ranging from local distorted knowledge to global perfect knowledge. In the case of local distorted knowledge, agents primarily rely on information from their first-degree colleagues. This knowledge is often distorted because agents are slow to update their empirical expectations, which are only partially revised after one-to-one interactions. On the other end of the spectrum, local perfect knowledge is achieved by incorporating a secondary source of information into the agents’ decision-making process. Here, accurate information provided by an observer is used to update empirical expectations.
The model shows that the same variation of the descriptive norm mechanism could lead to varying aggregate fraud levels across different fraud categories. Two empirically measured norm sensitivity distributions associated with different fraud categories can be selected into the model to see the different aggregate outcomes.
SMILI: Small-scale fisheries Institutions and Local Interactions
Emilie Lindkvist Maja Schlüter Xavier Basurto | Published Thursday, March 09, 2017The model represents an archetypical fishery in a co-evolutionary social-ecological environment, capturing different dimensions of trust between fishers and fish buyers for the establishment and persistence of self-governance arrangements.
Fire-WCISG
Sven Christ | Published Saturday, July 25, 2026An integrated wildfire and urban growth model for informal settlements.
Fire-WCISG is developed to test the impact of different fire management strategies on the number and type of residents staying in an informal settlement, and the fire-dependent fynbos vegetation that it is next to.
The model uses a hybrid protection motivation theory, place attachment and Turner’s informal residents as described by Christ et al. (2023) (10.1016/j.habitatint.2023.102815), for the agents decision making. Wildland vegetation is based on published understanding of fynbos ecology.
…
Structural Luck: An Agent-Based Model of Workplace Career Dynamics
Yang Ou | Published Sunday, August 23, 2026Why do career outcomes in organizations follow highly skewed distributions when the individual traits presumed to drive success — competence, effort, and social skill — are approximately normally distributed in the population? This agent-based model investigates the relative contributions of individual attributes versus random events (“luck”) to career outcomes in hierarchically structured organizations.
The model places 500 agents in a five-level pyramid-shaped organization over 80 six-month evaluation periods (40 simulated years). Each agent is characterized by four attributes drawn from normal distributions at initialization: competence, effort, social skill, and adaptability. In each period, agents may encounter stochastic career events (good or bad projects, supportive or poor managers, market booms or busts), which modify their performance and visibility scores. Promotion decisions are made competitively when vacancies arise at higher levels, using a weighted combination of recent performance, accumulated visibility, network position, and tenure. Social connections form and decay through a proximity-based model influenced by agents’ social skills.
The model extends the talent-versus-luck framework of Pluchino et al. (2018) in four substantive directions: (1) it embeds agents in a hierarchical organization with finite positions at each level, making promotion a zero-sum competition rather than an abstract encounter with random events; (2) it represents individual differences along four independent attribute dimensions rather than a single talent score; (3) it incorporates dynamic social network formation that mediates access to career-relevant opportunities; and (4) it implements the Peter Principle mechanism through which promoted agents must acquire competence appropriate to their new role.
…
LogoClim: WorldClim in NetLogo
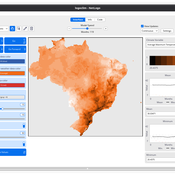
Daniel Vartanian Leandro Garcia Aline Martins de Carvalho Aline | Published Thursday, July 03, 2025 | Last modified Monday, July 13, 2026LogoClim is a NetLogo model designed to be integrated into other simulations through the LevelSpace extension (Hjorth et al., 2020), providing high resolution climate data from sources validated and used by the Intergovernmental Panel on Climate Change (IPCC).
The model simplifies and standardizes the integration of climate data into NetLogo, allowing researchers to focus their efforts on the model itself with the assurance of using reliable and widely recognized data. Although its main use is as a component of larger simulations, LogoClim also has its own graphical interface for monitoring and checking the datasets.
The climate data comes from the WorldClim 2.1 project (Fick & Hijmans, 2017), for which LogoClim works as an interface to NetLogo. The model supports all three WorldClim data series: (1) Historical Climate Data (1970 to 2000), with 12 monthly points for minimum, mean, and maximum temperature, precipitation, solar radiation, wind speed, vapor pressure, elevation, and bioclimatic variables; (2) Historical Monthly Weather Data (1951 to 2024), based on downscaling of CRU-TS-4.09, developed by the Climatic Research Unit at the University of East Anglia (Harris et al., 2020), with minimum and maximum temperature and total precipitation; and (3) Future Climate Data, based on downscaling climate projections derived from global climate models of the Coupled Model Intercomparison Project Phase 6 (CMIP6) (Eyring et al., 2016) for four future periods (2021 to 2040, 2041 to 2060, 2061 to 2080, and 2081 to 2100) and four scenarios based on the Shared Socioeconomic Pathways (SSPs 126, 245, 370, and 585), covering minimum and maximum temperature, total precipitation, and bioclimatic variables. All series are available at multiple spatial resolutions, from 10 minutes (about 340 km² at the equator) to 30 seconds (about 1 km² at the equator).
…
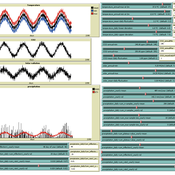
Peer reviewed The Indus Village's Weather model: procedural generation of daily weather
Andreas Angourakis | Published Tuesday, May 13, 2025Overview
The Weather model is a procedural generation model designed to create realistic daily weather data for socioecological simulations. It generates synthetic weather time series for solar radiation, temperature, and precipitation using algorithms based on sinusoidal and double logistic functions. The model incorporates stochastic variation to mimic unpredictable weather patterns and aims to provide realistic yet flexible weather inputs for exploring diverse climate scenarios.
The Weather model can be used independently or integrated into larger models, providing realistic weather patterns without extensive coding or data collection. It can be customized to meet specific requirements, enabling users to gain a better understanding of the underlying mechanisms and have greater confidence in their applications.
…
Peer reviewed Gradient Descent Simulation
Ilyes Azouani | Published Wednesday, March 18, 2026 | Last modified Monday, May 25, 2026This model visualizes gradient descent optimization - the fundamental algorithm used to train neural networks and other machine learning models. Agents represent different optimization algorithms searching for the minimum of a loss landscape (the “error surface” that ML models try to minimize during training).
The model demonstrates how different optimizer types (SGD, Momentum with different parameters) behave on various loss landscapes, from simple bowls to the notoriously difficult Rosenbrock “banana valley” function. This helps build intuition about why certain optimization algorithms work better than others for different problem geometries.
HOW IT WORKS
…
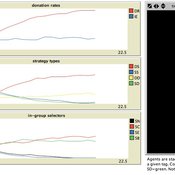
EthnoCultural Tag model (ECT)
Bruce Edmonds David Hales | Published Friday, October 16, 2015 | Last modified Wednesday, May 09, 2018Captures interplay between fixed ethnic markers and culturally evolved tags in the evolution of cooperation and ethnocentrism. Agents evolve cultural tags, behavioural game strategies and in-group definitions. Ethnic markers are fixed.
Peer reviewed MOOvPOPsurveillance
Matthew Gompper Aniruddha Belsare Joshua J Millspaugh | Published Tuesday, April 04, 2017 | Last modified Tuesday, May 12, 2020MOOvPOPsurveillance was developed as a tool for wildlife agencies to guide collection and analysis of disease surveillance data that relies on non-probabilistic methods like harvest-based sampling.
Displaying 10 of 204 results for "Kasper H Kisjes" clear search