Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 371 results for "Emmanuel Mhike Hove" clear search
Sensitivity of a population submitted to floods to unknown upcoming floods and parameters of the dynamics
Sylvie Huet | Published Wednesday, September 22, 2021This work is a java implementation of a study of the viability of a population submitted to floods. The population derives some benefit from living in a certain environment. However, in this environment, floods can occur and cause damage. An individual protection measure can be adopted by those who wish and have the means to do so. The protection measure reduces the damage in case of a flood. However, the effectiveness of this measure deteriorates over time. Individual motivation to adopt this measure is boosted by the occurrence of a flood. Moreover, the public authorities can encourage the population to adopt this measure by carrying out information campaigns, but this comes at a cost. People’s decisions are modelled based on the Protection Motivation Theory (Rogers1975, Rogers 1997, Maddux1983) arguing that the motivation to protect themselves depends on their perception of risk, their capacity to cope with risk and their socio-demographic characteristics.
While the control designing proper informations campaigns to remain viable every time is computed in the work presented in https://www.comses.net/codebases/e5c17b1f-0121-4461-9ae2-919b6fe27cc4/releases/1.0.0/, the aim of the present work is to produce maps of probable viability in case the serie of upcoming floods is unknown as well as much of the parameters for the population dynamics. These maps are bi-dimensional, based on the value of known parameters: the current average wealth of the population and their actual or possible future annual revenues.
Designing Fulfilling and Productive Workdays: Effects of Task Meaningfulness Sequences on Daily Engagement and Performance
S.R. Aurora (a.k.a. Mai P. Trinh) | Published Sunday, October 11, 2026Given the importance of experiencing fulfilling and productive workdays, scholars have focused on ways to boost employees’ daily engagement and performance, suggesting this may be accomplished by increasing meaningfulness of their work tasks. However, an alternative approach may be needed in multifaceted work contexts where employees need to complete sets of varied tasks each day, including tasks that lack meaningfulness. To address this issue, we integrate the workday design perspective with research on residual engagement to examine implications of strategically sequencing tasks in terms of their meaningfulness. We theorize that because of a process we refer to as engagement cascade, performing the day’s most highly meaningful tasks earlier and in a concentrated manner will tend to produce higher levels of daily engagement relative to sequences in which the most highly meaningful tasks occur later or are disbursed. We use agent-based modeling to formalize the engagement cascade process and generate specific predictions regarding how daily engagement is impacted by different task meaningfulness sequences. Findings from an intensive longitudinal design study with NASA and ROSCOSMOS crew members (Study 1), an experience sampling field experiment with full-time employees (Study 2), and two controlled laboratory experiments with undergraduates (Study 3 and Supplement to Study 3) provide support for our hypotheses. Specifically, the decreasing task meaningfulness sequence engendered higher levels of daily engagement, and in turn, daily performance, relative to increasing, inverted U-shaped, and U-shaped sequences.
ABODE - Agent Based Model of Origin Destination Estimation
D Levinson | Published Monday, August 29, 2011 | Last modified Saturday, April 27, 2013The agent based model matches origins and destinations using employment search methods at the individual level.
WealthDistribRes
Romulus-Catalin Damaceanu | Published Friday, May 04, 2012 | Last modified Saturday, April 27, 2013This model WealthDistribRes can be used to study the distribution of wealth in function of using a combination of resources classified in two renewable and nonrenewable.
Informal Information Transmission Networks among Medieval Genoese Investors
Christopher Frantz | Published Wednesday, October 09, 2013 | Last modified Thursday, October 24, 2013This model represents informal information transmission networks among medieval Genoese investors used to inform each other about cheating merchants they employed as part of long-distance trade operations.
Peer Review with Multiple Reviewers
Flaminio Squazzoni Federico Bianchi | Published Thursday, September 10, 2015This ABM looks at the effect of multiple reviewers and their behavior on the quality and efficiency of peer review. It models a community of scientists who alternatively act as “author” or “reviewer” at each turn.
The Effects of Fiscal Targets in a Currency Union: a Multi-Country Agent Based-Stock Flow Consistent Model
Ermanno Catullo Alessandro Caiani Mauro Gallegati | Published Saturday, March 11, 2017We present an Agent-Based Stock Flow Consistent Multi-Country model of a Currency Union to analyze the impact of changes in the fiscal regimes that is permanent changes in the deficit-to-GDP targets that governments commit to comply.
Livestock drought insurance model
Birgit Müller Felix John Jürgen Groeneveld Karin Frank Russell Toth | Published Tuesday, December 19, 2017 | Last modified Saturday, April 14, 2018The model analyzes the economic and ecological effects of a provision of livestock drought insurance for dryland pastoralists. More precisely, it yields qualitative insights into how long-term herd and pasture dynamics change through insurance.
This model extends the original Artifical Anasazi (AA) model to include individual agents, who vary in age and sex, and are aggregated into households. This allows more realistic simulations of population dynamics within the Long House Valley of Arizona from AD 800 to 1350 than are possible in the original model. The parts of this model that are directly derived from the AA model are based on Janssen’s 1999 Netlogo implementation of the model; the code for all extensions and adaptations in the model described here (the Artificial Long House Valley (ALHV) model) have been written by the authors. The AA model included only ideal and homogeneous “individuals” who do not participate in the population processes (e.g., birth and death)–these processes were assumed to act on entire households only. The ALHV model incorporates actual individual agents and all demographic processes affect these individuals. Individuals are aggregated into households that participate in annual agricultural and demographic cycles. Thus, the ALHV model is a combination of individual processes (birth and death) and household-level processes (e.g., finding suitable agriculture plots).
As is the case for the AA model, the ALHV model makes use of detailed archaeological and paleoenvironmental data from the Long House Valley and the adjacent areas in Arizona. It also uses the same methods as the original model (from Janssen’s Netlogo implementation) to estimate annual maize productivity of various agricultural zones within the valley. These estimates are used to determine suitable locations for households and farms during each year of the simulation.
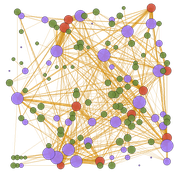
Peer reviewed TRANSOPE: a multi-agent model to simulate outsourcing networks in road freight transport.
Aitor Salas-Peña Blanca Rosa Cases Gutiérrez | Published Friday, October 21, 2022A road freight transport (RFT) operation involves the participation of several types of companies in its execution. The TRANSOPE model simulates the subcontracting process between 3 types of companies: Freight Forwarders (FF), Transport Companies (TC) and self-employed carriers (CA). These companies (agents) form transport outsourcing chains (TOCs) by making decisions based on supplier selection criteria and transaction acceptance criteria. Through their participation in TOCs, companies are able to learn and exchange information, so that knowledge becomes another important factor in new collaborations. The model can replicate multiple subcontracting situations at a local and regional geographic level.
The succession of n operations over d days provides two types of results: 1) Social Complex Networks, and 2) Spatial knowledge accumulation environments. The combination of these results is used to identify the emergence of new logistics clusters. The types of actors involved as well as the variables and parameters used have their justification in a survey of transport experts and in the existing literature on the subject.
As a result of a preferential selection process, the distribution of activity among agents shows to be highly uneven. The cumulative network resulting from the self-organisation of the system suggests a structure similar to scale-free networks (Albert & Barabási, 2001). In this sense, new agents join the network according to the needs of the market. Similarly, the network of preferential relationships persists over time. Here, knowledge transfer plays a key role in the assignment of central connector roles, whose participation in the outsourcing network is even more decisive in situations of scarcity of transport contracts.
Displaying 10 of 371 results for "Emmanuel Mhike Hove" clear search