Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 60 results for "Peter Sloep" clear search
When should professional-development places be concentrated
yuhouchunsun | Published Sunday, October 25, 2026This Python agent-based model simulates the diffusion of instructional practices among primary-school science teachers connected through within-school and cross-school networks. It represents teachers as agents nested in schools and compares five adoption mechanisms: simple contagion, proportion thresholds, count thresholds, adaptive norm conformity, and an individual-only baseline. The model evaluates fixed-budget training allocations, including concentrated and distributed policies, and estimates when school-level dose-response evidence can support targeted allocation. Experiments examine peer interference, cross-school contact intensity, global critical transitions, allocation stability, and the distinction between participant-level and system-level outcomes. Teacher attributes are informed by a de-identified Beijing questionnaire, whereas team sizes and contact networks are explicit model assumptions. The package includes executable Python scripts, ODD documentation, parameter tables, experiment metadata, simulation outputs, and the authorized questionnaire workbook required to reproduce the questionnaire-informed analyses. Results are intended as model-based design evidence for future longitudinal research rather than forecasts of adoption rates.
CONSERVAT
Pieter Van Oel | Published Monday, April 13, 2015The CONSERVAT model evaluates the effect of social influence among farmers in the Lake Naivasha basin (Kenya) on the spatiotemporal diffusion pattern of soil conservation effort levels and the resulting reduction in lake sedimentation.
Peer reviewed Descriptive Norm and Fraud Dynamics
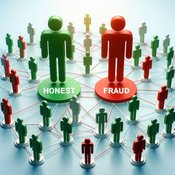
Alexandra Eckert Matthias Meyer Christian Stindt | Published Tuesday, January 07, 2025 | Last modified Tuesday, March 24, 2026The “Descriptive Norm and Fraud Dynamics” model demonstrates how fraudulent behavior can either proliferate or be contained within non-hierarchical organizations, such as peer networks, through social influence taking the form of a descriptive norm. This model expands on the fraud triangle theory, which posits that an individual must concurrently possess a financial motive, perceive an opportunity, and hold a pro-fraud attitude to engage in fraudulent activities (red agent). In the absence of any of these elements, the individual will act honestly (green agent).
The model explores variations in a descriptive norm mechanism, ranging from local distorted knowledge to global perfect knowledge. In the case of local distorted knowledge, agents primarily rely on information from their first-degree colleagues. This knowledge is often distorted because agents are slow to update their empirical expectations, which are only partially revised after one-to-one interactions. On the other end of the spectrum, local perfect knowledge is achieved by incorporating a secondary source of information into the agents’ decision-making process. Here, accurate information provided by an observer is used to update empirical expectations.
The model shows that the same variation of the descriptive norm mechanism could lead to varying aggregate fraud levels across different fraud categories. Two empirically measured norm sensitivity distributions associated with different fraud categories can be selected into the model to see the different aggregate outcomes.
MASTOC-LLM (Multi-Agent System Tragedy of the Commons - Large Language Models)
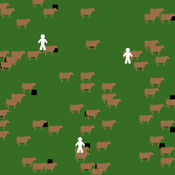
Thomas Tuoti | Published Monday, May 18, 2026 | Last modified Tuesday, May 19, 2026MASTOC-LLM extends the classic Multi-Agent System Tragedy of the Commons (MASTOC) model by replacing hard-coded behavioral rules with autonomous decision-making powered by large language models (LLMs). Three heterogeneous agents manage herds of cows on a shared grassland commons. Each tick, an agent receives a structured prompt describing current resource levels, its own herd size, peer behavior, and — optionally — a rolling memory of recent rounds and messages from neighboring agents. The LLM returns a stocking decision (add, remove, or hold cows) together with a natural-language rationale and, when communication is enabled, a short message to broadcast to peers.
The model is designed to test whether LLM agents spontaneously develop Ostrom-style common-pool resource governance (mutual monitoring, graduated sanctions, graduated rule revision) or instead fall into identifiable failure modes. Preliminary experiments with Claude Haiku 4.5, GPT-5.4-mini, and DeepSeek R1:32b have revealed four recurring collapse patterns — Cooperative Paralysis, Defection Cascade, Overshoot-Panic, and Hybrid Architecture Failure — whose onset timing is sensitive to memory length, inter-agent communication, and the post-training alignment approach of the underlying model.
MASTOC-LLM is intended as a laboratory for generative agent-based modelling (GABM) methodology: it provides a clean, well-understood commons baseline against which LLM behavioral hypotheses can be systematically tested and compared across models, parameter sweeps, and alignment regimes.
AnimDens NetLogo
Miguel Pais Christine Ward-Paige | Published Friday, February 10, 2017 | Last modified Sunday, February 23, 2020The model demonstrates how non-instantaneous sampling techniques produce bias by overestimating the number of counted animals, when they move relative to the person counting them.
Urban Teacher Lifecycle and Mobility
Yevgeny Patarakin | Published Wednesday, July 23, 2025This agent-based model simulates the lifecycle, movement, and satisfaction of teachers within an urban educational system composed of multiple universities and schools. Each teacher agent transitions through several possible roles: newcomer, university student, unemployed graduate, and employed teacher. Teachers’ pathways are shaped by spatial configuration, institutional capacities, individual characteristics, and dynamic interactions with schools and universities. Universities are assigned spatial locations with a controllable level of centralization and are characterized by academic ratings, capacity, and alumni records. Schools are distributed throughout the city, each with a limited number of vacancies, hiring requirements, and offered salaries. Teachers apply to universities based on the alignment of their personal academic profiles with institutional ratings, pursue studies, and upon graduation become candidates for employment at schools.
The employment process is driven by a decentralized matching of teacher expectations and school offers, taking into account factors such as salary, proximity, and peer similarity. Teachers’ satisfaction evolves over time, reflecting both institutional characteristics and the composition of their colleagues; low satisfaction may prompt teachers to transfer between schools within their mobility radius. Mortality and teacher attrition further shape workforce dynamics, leading to continuous recruitment of newcomers to maintain a stable population. The model tracks university reputation through the academic performance and number of alumni, and visualizes key metrics including teacher status distribution, school staffing, university alumni counts, and overall satisfaction. This structure enables the exploration of policy interventions, hiring and training strategies, and the impact of spatial and institutional design on the allocation, retention, and happiness of urban educational staff.
The SAFIRe model : Simulation of Agents for Fertility, Integrated Energy, Food security, and Reforestation
Etienne DELAY Lucas Broutin | Published Thursday, June 12, 2025The SAFIRe model (Simulation of Agents for Fertility, Integrated Energy, Food Security, and Reforestation) is an agent-based model co-developed with rural communities in Senegal’s Groundnut Basin. Its purpose is to explore how local farming and pastoral practices affect the regeneration of Faidherbia albida trees, which are essential for maintaining soil fertility and supporting food security through improved millet production. The model supports collective reflection on how different social and ecological factors interact, particularly around firewood demand, livestock pressure, and agricultural intensification.
The model simulates a 100-hectare agricultural landscape where agents (farmers, shepherds, woodcutters, and supervisors) interact with trees, land parcels, and each other. It incorporates seasonality, crop rotation, tree growth and cutting, livestock feeding behaviors, and farmers’ engagement in sapling protection through Assisted Natural Regeneration (ANR). Two types of surveillance strategies are compared: community-led monitoring and delegated surveillance by forestry authorities. Farmer engagement evolves over time based on peer influence, meeting participation, and the success of visible tree regeneration efforts.
SAFIRe integrates participatory modeling (ComMod and ComExp) and a backcasting approach (ACARDI) to co-produce scenarios rooted in local aspirations. It was explored using the OpenMole platform, allowing stakeholders to test a wide range of future trajectories and analyze the sensitivity of key parameters (e.g., discussion frequency, time in fields). The model’s outcomes not only revealed unexpected insights—such as the hidden role of farmers in tree loss—but also led to real-world actions, including community nursery creation and behavioral shifts toward tree care. SAFIRe illustrates how agent-based modeling can become a tool for social learning and collective action in socio-ecological systems.
User Guide and Templates for RAT-RS (a reporting standard for improving the documentation of data use in agent-based modelling)
Peer-Olaf Siebers Sebastian Achter Melania Borit Edmund Chattoe-Brown | Published Saturday, March 12, 2022The Rigor and Transparency Reporting Standard (RAT-RS) is a tool to improve the documentation of data use in Agent-Based Modelling. Following the development of reporting standards for models themselves, attention to empirical models has now reached a stage where these standards need to take equally effective account of data use (which until now has tended to be an afterthought to model description). It is particularly important that a standard should allow the reporting of the different uses to which data may be put (specification, calibration and validation), but also that it should be compatible with the integration of different kinds of data (for example statistical, qualitative, ethnographic and experimental) sometimes known as mixed methods research.
For the full details on the RAT-RS, please refer to the related publication “RAT-RS: A Reporting Standard for Improving the Documentation of Data Use in Agent-Based Modelling” (http://dx.doi.org/10.1080/13645579.2022.2049511).
Here we provide supplementary material for this article, consisting of a RAT-RS user guide and RAT-RS templates.
An Agent-Based Simulation of Continuous-Time Public Goods Games
Tuong Manh Vu | Published Thursday, May 17, 2018 | Last modified Tuesday, April 02, 2019To our knowledge, this is the first agent-based simulation of continuous-time PGGs (where participants can change contributions at any time) which are much harder to realise within both laboratory and simulation environments.
Work related to this simulation has been published in the following journal article:
Vu, Tuong Manh, Wagner, Christian and Siebers, Peer-Olaf (2019) ‘ABOOMS: Overcoming the Hurdles of Continuous-Time Public Goods Games with a Simulation-Based Approach’ Journal of Artificial Societies and Social Simulation 22 (2) 7 http://jasss.soc.surrey.ac.uk/22/2/7.html. doi: 10.18564/jasss.3995
Abstract:
…
Peer reviewed Gradient Descent Simulation
Ilyes Azouani | Published Wednesday, March 18, 2026 | Last modified Monday, May 25, 2026This model visualizes gradient descent optimization - the fundamental algorithm used to train neural networks and other machine learning models. Agents represent different optimization algorithms searching for the minimum of a loss landscape (the “error surface” that ML models try to minimize during training).
The model demonstrates how different optimizer types (SGD, Momentum with different parameters) behave on various loss landscapes, from simple bowls to the notoriously difficult Rosenbrock “banana valley” function. This helps build intuition about why certain optimization algorithms work better than others for different problem geometries.
HOW IT WORKS
…
Displaying 10 of 60 results for "Peter Sloep" clear search