No bio entered.
Artificial Anasazi: Baseline Fixes, Dynamic Soil and Plot Crowding
Thomas Tuoti | Published Sunday, October 04, 2026Artificial Anasazi is an agent-based model of farming households in the Long House Valley, Arizona, from 800 to 1350 CE. Each household chooses where to farm and settle based on expected harvest, water sources and stored maize, and simulated household counts are compared with the archaeological record.
This release adapts the NetLogo Models Library version (Stonedahl & Wilensky 2010) of Janssen’s (2009) NetLogo replication of the original Ascape model (Dean et al. 2000; Axtell et al. 2002). It contains four configurations in one NetLogo 7.0.4 file, selected with two switches:
- Both switches off: the baseline, which is the Models Library model with small fixes that make it work as intended (the arable-uplands zone name, the setup base yield, the initial household count, one-tick-lag capacity reporting, and seed control with observation-only instruments).
soil-on?: dynamic soil quality that depletes under cultivation and regrows, following Janssen (2010, eq. 4).
…
MASTOC-LLM (Multi-Agent System Tragedy of the Commons - Large Language Models)
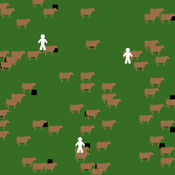
Thomas Tuoti | Published Monday, May 18, 2026 | Last modified Tuesday, May 19, 2026MASTOC-LLM extends the classic Multi-Agent System Tragedy of the Commons (MASTOC) model by replacing hard-coded behavioral rules with autonomous decision-making powered by large language models (LLMs). Three heterogeneous agents manage herds of cows on a shared grassland commons. Each tick, an agent receives a structured prompt describing current resource levels, its own herd size, peer behavior, and — optionally — a rolling memory of recent rounds and messages from neighboring agents. The LLM returns a stocking decision (add, remove, or hold cows) together with a natural-language rationale and, when communication is enabled, a short message to broadcast to peers.
The model is designed to test whether LLM agents spontaneously develop Ostrom-style common-pool resource governance (mutual monitoring, graduated sanctions, graduated rule revision) or instead fall into identifiable failure modes. Preliminary experiments with Claude Haiku 4.5, GPT-5.4-mini, and DeepSeek R1:32b have revealed four recurring collapse patterns — Cooperative Paralysis, Defection Cascade, Overshoot-Panic, and Hybrid Architecture Failure — whose onset timing is sensitive to memory length, inter-agent communication, and the post-training alignment approach of the underlying model.
MASTOC-LLM is intended as a laboratory for generative agent-based modelling (GABM) methodology: it provides a clean, well-understood commons baseline against which LLM behavioral hypotheses can be systematically tested and compared across models, parameter sweeps, and alignment regimes.
Under development.