Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 140 results for "Edward L Boone" clear search
Peer reviewed Axelrod_Cultural_Dissemination
Arezky Hernández | Published Wednesday, March 27, 2013 | Last modified Sunday, May 05, 2013The Axelrod’s model of cultural dissemination is an agent-model designed to investigate the dissemination of culture among interacting agents on a society.
Hedonic and Eudaimonic Well-being Based Reward for Intrinsic Motivated Reinforcement Learning Agents
Yue Gao Shimon Edelman | Published Monday, March 21, 2016The code contains four experiments for well-being based IMRL reward features.
Spatial model of the noisy Prisoner's Dilemma with reward shift
Matus Halas | Published Thursday, March 05, 2015 | Last modified Tuesday, May 29, 2018Interactions of players embedded in a closed square lattice are determined by distance and overall gains and they lead to shifts of reward payoff between temptation and punishment. A new winner balancing against threats is ultimately discovered.
Zombies
Jennifer Badham | Published Tuesday, June 08, 2021Zombies move toward humans and humans move (faster) away from zombies. They fight if they meet, and humans who lose become zombies.
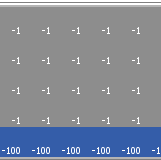
Cliff Walking with Q-Learning NetLogo Extension
Kevin Kons Fernando Santos | Published Tuesday, December 10, 2019This model implements a classic scenario used in Reinforcement Learning problem, the “Cliff Walking Problem”. Consider the gridworld shown below (SUTTON; BARTO, 2018). This is a standard undiscounted, episodic task, with start and goal states, and the usual actions causing movement up, down, right, and left. Reward is -1 on all transitions except those into the region marked “The Cliff.” Stepping into this region incurs a reward of -100 and sends the agent instantly back to the start (SUTTON; BARTO, 2018).
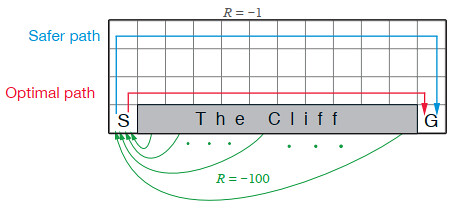
The problem is solved in this model using the Q-Learning algorithm. The algorithm is implemented with the support of the NetLogo Q-Learning Extension
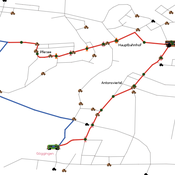
Simulating changing traffic flow caused by new bus route in Augsburg
Eduard | Published Wednesday, August 04, 2021This is a Netlogo model which simulates car and bus/tram traffic in Augsburg, specifically between the districts Stadtbergen, Göggingen and the Königsplatz. People either use their cars or public transport to travel to one of their random destinations (Stadtbergen or Göggingen), performing some activity and then returning to their home. Attributes such as travel and waiting time as well as their happiness upon arriving are stored and have an impact on individuals on whether they would consider changing their mode of transport or not.
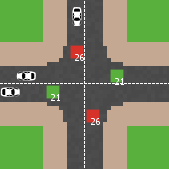
Modelling an intersection with traffic signal countdown timer
Eduard | Published Thursday, May 19, 2022Developed as a part of a project in the University of Augsburg, Institute of Geography, it simulates the traffic in an intersection or junction which uses either regular traffic lights or traffic lights with a countdown timer. The model tracks the average speed of cars before and after traffic lights as well as the throughput.
Peer reviewed MOSAIC: Mission-Oriented Self-Organization through Auctions, Incentives, and Coalitions
Katherin Molina Lorena Holguin | Published Friday, July 31, 2026 | Last modified Thursday, August 20, 2026MOSAIC is an agent-based NetLogo model of decentralized mission coordination among heterogeneous robots operating under partial observability, limited energy, spatially variable risk, dynamic communication, and individual and cooperative task requirements. Robots discover tasks locally, exchange task information through temporary communication links, submit capability-, energy-, deadline-, and risk-aware bids, compete for individual contracts, and form temporary coalitions for cooperative tasks.
The model integrates decentralized auctions, greedy capability-based coalition formation, contract release and reassignment, four reward regimes, reputation, adaptive bidding strategies, failure traceability, and mission-, network-, information-, inequality-, and coalition-level metrics. It operates without a centralized mission planner or global combinatorial assignment solver.
Seven paired-seed BehaviorSpace experiments comprising 690 official simulation runs evaluate baseline mission viability, reward regimes, communication structure, capability heterogeneity, cooperative-task demand, reputation and adaptive strategies, and mission-incentive strength. The results indicate that structural coordination capacity—particularly information reach, capability compatibility, and feasible coalition construction—has a stronger effect on mission completion than increasing incentive intensity within the tested architecture and parameter ranges.
…
PredPreyGrass
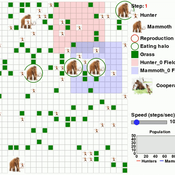
HBP1969 | Published Sunday, May 17, 2026Exploring learned cooperation, coevolution and free-riding. Learning is achieved through Multi-Agent Deep Reinforcement Learning (MADRL) in an ecological environment. The environment emits no other than sparse reproduction rewards. No reward shaping, no explicit cooperation signal.
IDEAL
Arika Ligmann-Zielinska | Published Thursday, August 07, 2014IDEAL: Agent-Based Model of Residential Land Use Change where the choice of new residential development in based on the Ideal-point decision rule.
Displaying 10 of 140 results for "Edward L Boone" clear search