Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 1018 results for "Wilfried van Sark" clear search
Knowledge Sharing in a Hospital
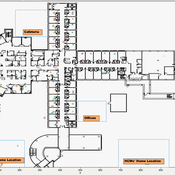
bpint Emily Molfino Joshua Goldstein Kathryn Schaefer Ziemer Mark Orr Bryan Lewis Jose Jimenez | Published Friday, January 27, 2023Organizations are complex systems comprised of many dynamic and evolving interaction patterns among individuals and groups. Understanding these interactions and how patterns, such as informal structures and knowledge sharing behavior, emerge are crucial to creating effective and efficient organizations. To explore such organizational dynamics, the agent-based model integrates a cognitive model, dynamic social networks, and a physical environment.
Peer reviewed HUMLAND2: HUMan impact on LANDscapes agent-based model
Anastasia Nikulina Anhelina Zapolska Maria Antonia Serge Marco Davoli Dave van Wees Katharine MacDonald Elena A. Pearce Fulco Scherjon | Published Friday, August 30, 2024The HUMan Impact on LANDscapes (HUMLAND) 2.0.0 is an enhanced version of HUMLAND 1.0.0, developed to track and quantify the intensity of various impacts on landscapes at a continental scale. The model is designed to identify the most influential factors in the transformation of interglacial vegetation, with a particular focus on the burning practices of hunter-gatherers. HUMLAND 2.0.0 incorporates a wide range of spatial datasets as both inputs and targets (expected modelling results) for simulations across Last Interglacial (~130,000–116,000 BP) and Early Holocene (~11,700–8,000 BP).
Peer reviewed HUMLAND: HUMan impact on LANDscapes agent-based model
Anastasia Nikulina Katharine MacDonald Anhelina Zapolska Maria Antonia Serge Marco Davoli Dave van Wees Fulco Scherjon | Published Monday, October 16, 2023The HUMan impact on LANDscapes (HUMLAND) model has been developed to track and quantify the intensity of different impacts on landscapes at the continental level. This agent-based model focuses on determining the most influential factors in the transformation of interglacial vegetation with a specific emphasis on burning organized by hunter-gatherers. HUMLAND integrates various spatial datasets as input and target for the agent-based model results. Additionally, the simulation incorporates recently obtained continental-scale estimations of fire return intervals and the speed of vegetation regrowth. The obtained results include maps of possible scenarios of modified landscapes in the past and quantification of the impact of each agent, including climate, humans, megafauna, and natural fires.
Mission San Diego Model
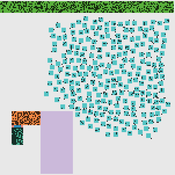
Carolyn Orbann | Published Monday, April 15, 2019The Mission San Diego model is an epidemiological model designed to test hypotheses related to the spread of the 1805-1806 measles epidemic among indigenous residents of Mission San Diego during the early mission period in Alta California. The model community is based on the population of the Mission San Diego community, as listed in the parish documents (baptismal, marriage, and death records). Model agents are placed on a map-like grid that consists of houses, the mission church, a women’s dormitory (monjeria) adjacent to the church, a communal kitchen, priest’s quarters, and agricultural fields. They engage in daily activities that reflect known ethnographic patterns of behavior at the mission. A pathogen is introduced into the community and then it spreads throughout the population as a consequence of individual agent movements and interactions.
Peer reviewed Virus Transmission with Super-spreaders
J M Applegate | Published Saturday, September 11, 2021A curious aspect of the Covid-19 pandemic is the clustering of outbreaks. Evidence suggests that 80\% of people who contract the virus are infected by only 19% of infected individuals, and that the majority of infected individuals faile to infect another person. Thus, the dispersion of a contagion, $k$, may be of more use in understanding the spread of Covid-19 than the reproduction number, R0.
The Virus Transmission with Super-spreaders model, written in NetLogo, is an adaptation of the canonical Virus Transmission on a Network model and allows the exploration of various mitigation protocols such as testing and quarantines with both homogenous transmission and heterogenous transmission.
The model consists of a population of individuals arranged in a network, where both population and network degree are tunable. At the start of the simulation, a subset of the population is initially infected. As the model runs, infected individuals will infect neighboring susceptible individuals according to either homogenous or heterogenous transmission, where heterogenous transmission models super-spreaders. In this case, k is described as the percentage of super-spreaders in the population and the differing transmission rates for super-spreaders and non super-spreaders. Infected individuals either recover, at which point they become resistant to infection, or die. Testing regimes cause discovered infected individuals to quarantine for a period of time.
Peer reviewed Descriptive Norm and Fraud Dynamics
Alexandra Eckert Matthias Meyer Christian Stindt | Published Tuesday, January 07, 2025 | Last modified Tuesday, March 24, 2026The “Descriptive Norm and Fraud Dynamics” model demonstrates how fraudulent behavior can either proliferate or be contained within non-hierarchical organizations, such as peer networks, through social influence taking the form of a descriptive norm. This model expands on the fraud triangle theory, which posits that an individual must concurrently possess a financial motive, perceive an opportunity, and hold a pro-fraud attitude to engage in fraudulent activities (red agent). In the absence of any of these elements, the individual will act honestly (green agent).
The model explores variations in a descriptive norm mechanism, ranging from local distorted knowledge to global perfect knowledge. In the case of local distorted knowledge, agents primarily rely on information from their first-degree colleagues. This knowledge is often distorted because agents are slow to update their empirical expectations, which are only partially revised after one-to-one interactions. On the other end of the spectrum, local perfect knowledge is achieved by incorporating a secondary source of information into the agents’ decision-making process. Here, accurate information provided by an observer is used to update empirical expectations.
The model shows that the same variation of the descriptive norm mechanism could lead to varying aggregate fraud levels across different fraud categories. Two empirically measured norm sensitivity distributions associated with different fraud categories can be selected into the model to see the different aggregate outcomes.
Peer reviewed Garbage can model Excel reconstruction
Smarzhevskiy Ivan | Published Tuesday, August 19, 2014 | Last modified Tuesday, July 30, 2019Reconstruction of the original code M. Cohen, J. March, and J. Olsen garbage can model, realized by means of Microsoft Office Excel 2010
Peer reviewed Garbage can model NetLogo implementation
Smarzhevskiy Ivan | Published Sunday, February 14, 2016 | Last modified Tuesday, July 30, 2019It is NetLogo reconstruction of the original FORTRAN code of the classical M. Cohen, J. March, and J. Olsen “garbage can model” (GCM or CMO) of collective decision-making.
The Garbage Can Model - old version
Guido Fioretti | Published Saturday, June 22, 2013We reconstruct Cohen, March and Olsen’s Garbage Can model of organizational choice as an agent-based model. We add another means for avoiding making decisions: buck-passing difficult problems to colleagues.
Peer reviewed Organizational behavior in the hierarchy model
Smarzhevskiy Ivan | Published Tuesday, June 18, 2019 | Last modified Wednesday, July 31, 2019In a two-level hierarchical structure (consisting of the positions of managers and operators), persons holding these positions have a certain performance and the value of their own (personal perception in this, simplified, version of the model) perception of each other. The value of the perception of each other by agents is defined as a random variable that has a normal distribution (distribution parameters are set by the control elements of the interface).
In the world of the model, which is the space of perceptions, agents implement two strategies: rapprochement with agents that perceive positively and distance from agents that perceive negatively (both can be implemented, one of these strategies, or neither, the other strategy, which makes the agent stationary). Strategies are implemented in relation to those agents that are in the radius of perception (PerRadius).
The manager (Head) forms a team of agents. The performance of the group (the sum of the individual productivities of subordinates, weighted by the distance from the leader) varies depending on the position of the agents in space and the values of their individual productivities. Individual productivities, in the current version of the model, are set as a random variable distributed evenly on a numerical segment from 0 to 100. The manager forms the team 1) from agents that are in (organizational) radius (Op_Radius), 2) among agents that the manager perceives positively and / or negatively (both can be implemented, one of the specified rules, or neither, which means the refusal of the command formation).
Agents can (with a certain probability, given by the variable PrbltyOfDecisn%), in case of a negative perception of the manager, leave his group permanently.
It is possible in the model to change on the fly radii values, update the perception value across the entire population and the perception of an individual agent by its neighbors within the perception radius, and the probability values for a subordinate to make a decision about leaving the group.
You can also change the set of strategies for moving agents and strategies for recruiting a team manager. It is possible to add a randomness factor to the movement of agents (Stoch_Motion_Speed, the default is set to 0, that is, there are no random movements).
…
Displaying 10 of 1018 results for "Wilfried van Sark" clear search