Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 281 results for "Carlos Andrés Chiale" clear search
Peer reviewed Casting: A Bio-Inspired Method for Restructuring Machine Learning Ensembles
Colin Lynch Bryan Daniels | Published Thursday, September 18, 2025The wisdom of the crowd refers to the phenomenon in which a group of individuals, each making independent decisions, can collectively arrive at highly accurate solutions—often more accurate than any individual within the group. This principle relies heavily on independence: if individual opinions are unbiased and uncorrelated, their errors tend to cancel out when averaged, reducing overall bias. However, in real-world social networks, individuals are often influenced by their neighbors, introducing correlations between decisions. Such social influence can amplify biases, disrupting the benefits of independent voting. This trade-off between independence and interdependence has striking parallels to ensemble learning methods in machine learning. Bagging (bootstrap aggregating) improves classification performance by combining independently trained weak learners, reducing bias. Boosting, on the other hand, explicitly introduces sequential dependence among learners, where each learner focuses on correcting the errors of its predecessors. This process can reinforce biases present in the data even if it reduces variance. Here, we introduce a new meta-algorithm, casting, which captures this biological and computational trade-off. Casting forms partially connected groups (“castes”) of weak learners that are internally linked through boosting, while the castes themselves remain independent and are aggregated using bagging. This creates a continuum between full independence (i.e., bagging) and full dependence (i.e., boosting). This method allows for the testing of model capabilities across values of the hyperparameter which controls connectedness. We specifically investigate classification tasks, but the method can be used for regression tasks as well. Ultimately, casting can provide insights for how real systems contend with classification problems.
Bargaining with misvaluation
Marcin Czupryna | Published Wednesday, January 14, 2026Subjective biases and errors systematically affect market equilibria, whether at the population level or in bilateral trading. Here, we consider the possibility that an agent engaged in bilateral trading is mistaken about her own valuation of the good she expects to trade, that has not been explicitly incorporated into the existing bilateral trade literature. Although it may sound paradoxical that a subjective private valuation is something an agent can be mistaken about, as it is up to her to fix it, we consider the case in which that agent, seller or buyer, consciously or not, given the structure of a market, a type of good, and a temporary lack of information, may arrive at an erroneous valuation. The typical context through which this possibility may arise is in relation with so-called experience goods, which are sold while all their intrinsic qualities are still unknown (such as untasted bottled fine wines). We model this “private misvaluation” phenomenon in our study. The agents may also be mistaken about how their exchange counterparties are themselves mistaken. Formally, they attribute a certain margin of error to the other agent, which can differ from the actual way that another agent misvalues the good under consideration. This can constitute the source of a second-order misvaluation. We model different attitudes and situations in which agents face unexpected signals from their counterparties and the manner and extent to which they revise their initial beliefs. We analyse and simulate numerically the consequences of first-order and second-order misvaluation on market equilibria.
Negotiation Lab 1.0
Julián Arévalo | Published Friday, March 20, 2026Negotiation Lab 1.0 is an agent-based model of peace negotiations that explores how the parties’ readiness — their motivation and optimism to engage in talks — evolves dynamically throughout the negotiation process. The model reconceptualizes readiness as an adaptive state variable that is continuously updated through feedback from negotiation outcomes, rather than a static precondition assessed at the onset of talks.
The model simulates two parties negotiating a multi-issue agenda. In each round, parties allocate effort to the current sub-issue; outcomes depend on their joint effort and a stochastic component representing external factors. Results feed back into each party’s readiness, shaping subsequent engagement. The negotiation ends either when all agenda items are resolved (agreement) or when a party’s readiness falls below a critical threshold (breakdown).
Key parameters include the initial readiness of each party, agenda structure (balanced, hard, easy, red, or random), type of negotiation (from highly cooperative to highly competitive), and each party’s effort strategy (always high, always low, random, or pseudo tit-for-tat). The model shows that while initial readiness is associated with negotiation outcomes, it is neither necessary nor sufficient to determine them: process variables — the type of interaction, agenda design, and adaptive effort strategies — exert comparatively larger effects on outcomes. Identical initial conditions can produce widely divergent trajectories, illustrating path dependence and sensitivity to feedback dynamics.
The model is implemented in NetLogo 7.0 and is documented using the ODD+D protocol. It is associated with the paper “Beyond Initial Conditions: How Adaptive Readiness Shapes Peace Negotiation Outcomes” (Arévalo, under review).
One Signal, Many Feeds: An Empirical-Response Agent-Based Model of Coordination Failure in Algorithmic Creator Discovery
Haocheng Wang | Published Thursday, August 06, 2026An empirical-response agent-based model of how many personalized feeds execute a shared low-exposure creator-discovery objective. Built from the KuaiRec dataset: the big interaction matrix initializes a transparent rank-8 matrix-factorization platform learner and the activity schedule, while the near-complete small matrix returns observed viewing responses only after a user-video pair is exposed. Four exploration policies (synchronous low-exposure targeting, uniform exploration, per-user random tie-breaking, capacity-balanced coordination) are compared over 28 rounds at a nominal 10% exploration budget, across 30 paired seeds (core) and 10 paired seeds (bias-only probe), with slot-level redundancy, cross-user collision, and coverage diagnostics.
This release accompanies an anonymised manuscript under review at the Journal of Artificial Societies and Social Simulation.
The model represents 1,411 users, 3,327 videos, 2,031 authors, and an adaptive platform over 28 discrete rounds derived from the KuaiRec big-matrix activity calendar. Exploration policies differ only in how a fixed 10% slot budget is allocated; all policies share the opportunity schedule, response oracle, initial checkpoints, and online update rule.
Archive contents: analysis pipeline scripts (01-16), frozen machine-readable protocols with input hashes, initial model checkpoints, aggregate result tables, the complete ODD protocol record, and publication figures. Raw KuaiRec files are not redistributed; obtain them from the official dataset repository and verify against the input hashes in data_contract/. Row-level oracle tables are excluded by design.
…
9 Maturity levels in Empirical Validation - An innovation diffusion example
Martin Rixin | Published Wednesday, October 19, 2011 | Last modified Saturday, April 27, 2013Several taxonomies for empirical validation have been published. Our model integrates different methods to calibrate an innovation diffusion model, ranging from simple randomized input validation to complex calibration with the use of microdata.
Agent-Based Model for the Evolution of Ethnocentrism
Max Hartshorn | Published Saturday, March 24, 2012 | Last modified Saturday, April 27, 2013This is an implementation of an agent based model for the evolution of ethnocentrism. While based off a model published by Hammond and Axelrod (2006), the code has been modified to allow for a more fine-grained analysis of evolutionary dynamics.
PSMED - Patagonia Simple Model of Ethnic Differentiation
Xavier Vilà Joan A Barceló J A Cuesta Florencia Del Castillo Ricardo Del Olmo José M Galán Laura Mameli Francisco J Miguel David Poza José I Santos | Published Tuesday, December 10, 2013Patagonia PSMED is an agent-based model designed to study a simple case of Evolution of Ethnic Differentiation. It replicates how can hunter-gatherer societies evolve and built cultural identities as a consequence of the way they interacted.
Gender differentiation model
Sylvie Huet | Published Monday, April 20, 2020 | Last modified Thursday, April 23, 2020This is a gender differentiation model in terms of reputations, prestige and self-esteem (presented in the paper https://journals.plos.org/plosone/article?id=10.1371/journal.pone.0236840). The model is based on the influence function of the Leviathan model (Deffuant, Carletti, Huet 2013 and Huet and Deffuant 2017) considering two groups.
This agent-based model studies how inequalities can be explained by the difference of open-mindness between two groups of interacting agents. We consider agents having an opinion/esteem about each other and about themselves. During dyadic meetings, agents change their respective opinion about each other and possibly about other agents they gossip about, with a noisy perception of the opinions of their interlocutor. Highly valued agents are more influential in such encounters. We study an heterogeneous population of two different groups: one more open to influence of others, taking less into account their perceived difference of esteem, called L; a second one less prone to it, called S, who designed the credibility they give to others strongly based on how higher or lower valued than themselves they perceive them.
We show that a mixed population always turns in favor to some agents belonging to the group of less open-minded agents S, and harms the other group: (1) the average group self-opinion or reputation of S is always better than the one of L; (2) the higher rank in terms of reputation are more frequently occupied by the S agents while the L agents occupy more the bottom rank; (3) the properties of the dynamics of differentiation between the two groups are similar to the properties of the glass ceiling effect proposed by Cotter et al (2001).
Seascapes of the Unreal: Using Agent Based Modeling to Examine Traditional Coast Salish Maritime Mobility
Adam Rorabaugh | Published Friday, December 22, 2023Non-traditional tools and mediums can provide unique methodological and interpretive opportunities for archaeologists. In this case, the Unreal Engine (UE), which is typically used for games and media, has provided a powerful tool for non-programmers to engage with 3D visualization and programming as never before. UE has a low cost of entry for researchers as it is free to download and has user-friendly “blueprint” tools that are visual and easily extendable. Traditional maritime mobility in the Salish Sea is examined using an agent-based model developed in blueprints. Focusing on the sea canoe travel of the Straits Salish northwestern Washington State and southwest British Columbia. This simulation integrates GIS data to assess travel time between Coast Salish archaeological village locations and archaeologically represented resource gathering areas. Transportation speeds informed by ethnographic data were used to examine travel times for short forays and longer inter-village journeys. The results found that short forays tended to half day to full day trips when accounting for resource gathering activities. Similarly, many locations in the Salish Sea were accessible in long journeys within two to three days, assuming fair travel conditions. While overall transportation costs to reach sites may be low, models such as these highlight the variability in transport risk and cost. The integration of these types of tools, traditionally used for entertainment, can increase the accessibility of modeling approaches to researchers, be expanded to digital storytelling, including aiding in the teaching of traditional ecological knowledge and placenames, and can have wide applications beyond maritime archaeology.
This is v0.01 of a UE5.2.1 agent based model.
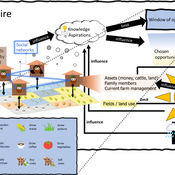
3spire: an agent-based model for exploring aspiration adaptation theory and its implications on smallholder farmers in Ethiopia
ateeuw Yue Dou Markus A Meyer Andrew Nelson | Published Sunday, February 16, 20253spire is an ABM where farming households make management decisions aimed at satisficing along the aspirational dimensions: food self-sufficiency, income, and leisure. Households decision outcomes depend on their social networks, knowledge, assets, household needs, past management, and climate/market trends
Displaying 10 of 281 results for "Carlos Andrés Chiale" clear search