Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 247 results for "netlogo" clear search
An empirical ABM for regional land use/cover change: a Dutch case study
Diego Valbuena | Published Saturday, March 12, 2011 | Last modified Thursday, November 11, 2021This is an empirical model described in http://dx.doi.org/10.1016/j.landurbplan.2010.05.001. The objective of the model is to simulate how the decision-making of farmers/agents with different strategies can affect the landscape structure in a region in the Netherlands.
MCR Model
Davide Secchi Nuno R Barros De Oliveira | Published Friday, July 22, 2016 | Last modified Saturday, January 23, 2021The aim of the model is to define when researcher’s assumptions of dependence or independence of cases in multiple case study research affect the results — hence, the understanding of these cases.
A simulation model for Dublin city
umesh7lowe | Published Friday, April 10, 2026An agent-based model of urban travel behaviour in Dublin, Ireland, built in NetLogo and empirically grounded in 2016 travel survey data. Each agent represents a Dublin resident initialised with real socio-demographic attributes — including age, gender, household size and car ownership, income, driving licence status, and access to local amenities — alongside observed trip characteristics such as distance, travel time, and trip type (work, shopping, leisure).
At each time step, agents choose between four transport modes (car, public transport, cycling, and walking) across short, medium, and long trips. Mode choice is governed by a preference vector that weighs personal need satisfaction against social influence from neighbouring agents reflecting consumat framework. Satisfaction evolves dynamically based on cost (incorporating Irish motor tax bands and per-km operating rates), travel time, and trip-type suitability, with an uncertainty parameter capturing variability in perceived utility over time.
The model tracks aggregate modal shares and total CO2 emission at each tick, enabling exploration of how policy interventions — such as fuel taxation, public transport pricing, or active travel incentives — might shift the city’s travel demand profile over 100 simulated days.
Neolithic Spread Model Version 1.0
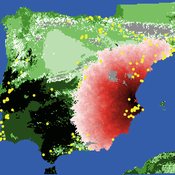
Sean Bergin Salvador Pardo Gordo Joan Bernabeu Auban Michael Barton | Published Thursday, December 11, 2014 | Last modified Monday, December 31, 2018This model simulates different spread hypotheses proposed for the introduction of agriculture on the Iberian peninsula. We include three dispersal types: neighborhood, leapfrog, and ideal despotic distribution (IDD).
An agent-based model of building occupant behavior during load shedding
Handi Chandra Putra | Published Thursday, May 21, 2020Load shedding enjoys increasing popularity as a way to reduce power consumption in buildings during hours of peak demand on the electricity grid. This practice has well known cost saving and reliability benefits for the grid, and the contracts utilities sign with their “interruptible” customers often pass on substantial electricity cost savings to participants. Less well-studied are the impacts of load shedding on building occupants, hence this study investigates those impacts on occupant comfort and adaptive behaviors. It documents experience in two office buildings located near Philadelphia (USA) that vary in terms of controllability and the set of adaptive actions available to occupants. An agent-based model (ABM) framework generalizes the case-study insights in a “what-if” format to support operational decision making by building managers and tenants. The framework, implemented in EnergyPlus and NetLogo, simulates occupants that have heterogeneous
thermal and lighting preferences. The simulated occupants pursue local adaptive actions such as adjusting clothing or using portable fans when central building controls are not responsive, and experience organizational constraints, including a corporate dress code and miscommunication with building managers. The model predicts occupant decisions to act fairly well but has limited ability to predict which specific adaptive actions occupants will select.
An Agent-Based Model for Skilled Workers Migration
Hassan Bashiri | Published Thursday, September 21, 2023This documentation provides an overview and explanation of the NetLogo simulation code for modeling skilled workers’ migration in Iran. The simulation aims to explore the dynamics of skilled workers’ migration and their transition through various states, including training, employment, and immigration.
The flow of elite and talent migration, or “brain drain,” is a complex issue with far-reaching implications for developing countries. The decision to migrate is made due to various factors including economic opportunities, political stability, social factors and personal circumstances.
Measuring individual interests in the field of immigration is a complex task that requires careful consideration of various factors. The agent-based model is a useful tool for understanding the complex factors that are involved in talent migration. By considering the various social, economic, and personal factors that influence migration decisions, policymakers can provide more effective strategies to retain skilled and talented labor and promote sustainable growth in developing countries. One of the main challenges in studying the flow of elite migration is the complexity of the decision-making process and a set of factors that lead to migration decisions. Agent-based modeling is a useful tool for understanding how individual decisions can lead to large-scale migration patterns.
Amber Dilemma Zone: Driver Cognition and Signal Control in Urban Traffic
Mansoor Abdul Bari | Published Sunday, July 19, 2026This model is an extension of Wilensky’s (2003) Traffic Grid, a foundational NetLogo model of urban traffic flow. It embeds a dual-process cognitive architecture into each driver agent, transforming the original’s identical reactive units into cognitively heterogeneous individuals whose internal mental state evolves with experience; making the same intersection produce different decisions from different drivers, and different decisions from the same driver across occasions.
The core question the model addresses is the yellow-light dilemma zone: the seconds following amber onset in which a driver can neither stop safely nor clear the intersection before red. Field research documents that behavioral variance at this moment cannot be explained by geometry or legal obligation alone. This model provides the cognitive architecture that has been missing from traffic ABMs.
Each driver routes every amber-onset decision through either System 1 (fast, heuristic, automatic) or System 2 (slow, deliberative, prospect-theoretic), switching dynamically based on cognitive load, accumulated near-miss memory, and situational framing. The result is crash outcomes that are attributable, path-dependent, and sensitive to both driver disposition and signal infrastructure; none of which fixed-rule models can reproduce. Three signal control modes are included: fixed-cycle (replicating Wilensky’s original), adaptive-queue, and smart occupancy-based switching.
A preliminary extension of the Hemelrijk 1996 model of reciprocal behavior to include feeding
Sean Barton | Published Monday, December 13, 2010 | Last modified Saturday, April 27, 2013A more complete description of the model can be found in Appendix I as an ODD protocol. This model is an expansion of the Hemelrijk (1996) that was expanded to include a simple food seeking behavior.
Peer reviewed Virus Transmission with Super-spreaders
J M Applegate | Published Saturday, September 11, 2021A curious aspect of the Covid-19 pandemic is the clustering of outbreaks. Evidence suggests that 80\% of people who contract the virus are infected by only 19% of infected individuals, and that the majority of infected individuals faile to infect another person. Thus, the dispersion of a contagion, $k$, may be of more use in understanding the spread of Covid-19 than the reproduction number, R0.
The Virus Transmission with Super-spreaders model, written in NetLogo, is an adaptation of the canonical Virus Transmission on a Network model and allows the exploration of various mitigation protocols such as testing and quarantines with both homogenous transmission and heterogenous transmission.
The model consists of a population of individuals arranged in a network, where both population and network degree are tunable. At the start of the simulation, a subset of the population is initially infected. As the model runs, infected individuals will infect neighboring susceptible individuals according to either homogenous or heterogenous transmission, where heterogenous transmission models super-spreaders. In this case, k is described as the percentage of super-spreaders in the population and the differing transmission rates for super-spreaders and non super-spreaders. Infected individuals either recover, at which point they become resistant to infection, or die. Testing regimes cause discovered infected individuals to quarantine for a period of time.
This is an agent-based model that simulates the structural evolution in food supply chain.
Displaying 10 of 247 results for "netlogo" clear search