Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 55 results quality clear search
The emergence of new market logics in sustainable food
César García-Díaz | Published Friday, October 30, 2026The model represents a large, traditional firm competing with small, sustainable food producers. The large firm operates under conventional assumptions, pursuing monopoly profits maximized through standard economic principles. Its behavior is driven by economies of scale, which compel small firms to strategically differentiate themselves to deliver added value to consumers. Consequently, small firms focus on offering higher-quality products—a factor that matters significantly to consumers.
The gains achieved by small firms represent social profits that hinge upon establishing co-participation schemes with farmers and building trustworthy relationships with consumers. Cooperation with farmers directly shapes production processes and product quality. Because a firm trusted by one consumer becomes visible to neighbors, trust can diffuse and evolve into a collective identity. Ultimately, population-level legitimation occurs when the organizational form of the organic food producer gains widespread acceptance within the consumer community.
The model’s behavior depends on three key factors: a trust parameter, a legitimation intensity parameter, and an aspiration-level weight (for the large firm).
Artificial Anasazi: Baseline Fixes, Dynamic Soil and Plot Crowding
Thomas Tuoti | Published Sunday, October 04, 2026Artificial Anasazi is an agent-based model of farming households in the Long House Valley, Arizona, from 800 to 1350 CE. Each household chooses where to farm and settle based on expected harvest, water sources and stored maize, and simulated household counts are compared with the archaeological record.
This release adapts the NetLogo Models Library version (Stonedahl & Wilensky 2010) of Janssen’s (2009) NetLogo replication of the original Ascape model (Dean et al. 2000; Axtell et al. 2002). It contains four configurations in one NetLogo 7.0.4 file, selected with two switches:
- Both switches off: the baseline, which is the Models Library model with small fixes that make it work as intended (the arable-uplands zone name, the setup base yield, the initial household count, one-tick-lag capacity reporting, and seed control with observation-only instruments).
soil-on?: dynamic soil quality that depletes under cultivation and regrows, following Janssen (2010, eq. 4).
…
NearshoreABM: production network formation under infrastructure constraints and financial frictions
Alejandro Platas López | Published Thursday, August 20, 2026NearshoreABM simulates whether a region captures the production linkages that nearshoring makes available, or fails to capture them because physical infrastructure and credit supply bind first.
The model runs over the 32 Mexican states at quarterly frequency. Multinational anchor firms decide whether to enter and where to locate, following Melitz selection on heterogeneous productivity under trade-policy uncertainty. Domestic supplier firms decide whether to formalise and whether to invest in quality, and may or may not obtain a contract with an anchor. A banking sector allocates a finite regional credit supply according to observed default risk, serving anchor firms before suppliers.
Electricity and water capacity enter production as non-linear congestion penalties with an engineering-based threshold, so the response of output to demand growth is discontinuous rather than proportional: below the threshold there is no penalty at all, between threshold and capacity the penalty grows quadratically, and above capacity it decays exponentially. Congestion is rivalrous within the quarter, which makes the order of production economically meaningful rather than incidental.
…
Genetic Algorithm and Food Choice
Diego Martín Díaz Córdova | Published Monday, August 10, 2026This models simulate how people choose their food buyings based on a limited budget and a food quality index. In order to make the choice the agents call a genetic algorithm who optimizes the buying. The agents are distributed randomly and there are 5 store options where agents can buy meat, fruits and vegetables, bread, ultraprocessed and medications. Agents need all of them, each of one has a different price and a different quality index. The genetic algorithm perform an optimization procedure in order to clasiffy what food set is the best for each agent. The agents are coloured based on their budget if the’ve got less than 100, then they are pink otherwise they are white.
Peer reviewed Collective Problem-Solving Capacity, Trust, and O-Ring Team Productivity
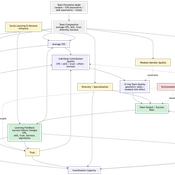
Taseer Salahuddin Hasan Vergil Muhammad Abdullah Yasser | Published Saturday, August 08, 2026This is a NetLogo 7.0.1 agent-based model of interdependent team productivity under O-ring production logic. The model asks when collective problem-solving capacity (CPS) improves team output and when its effect is constrained by trust, burnout, specialization diversity, weak-link quality, and team-formation rules. Agents are heterogeneous in skill, CPS, trust, burnout, effort, learning rate, openness, specialization, adaptability, and aspiration. Each tick forms temporary teams, computes individual contribution quality, combines contributions through a geometric O-ring production function with an explicit weakest-link term, records output and success, and updates agents through feedback, learning, trust change, burnout, recovery, and turnover. The paper follows the ODD protocol, reports exact implementation equations, and analyzes six BehaviorSpace experiments with 50 stochastic repetitions per condition. Scenario results show that CPS is beneficial but not sufficient: productivity is highest when CPS is combined with trust, low burnout, effective coordination, and a reliable weakest-link floor. Diversity yields only modest gains at low CPS but larger gains when CPS is high. Formation-mode results are especially informative because mixed CPS-skill formation maximizes total output, whereas random formation has the highest binary success rate, showing that output magnitude and threshold success can diverge. The study contributes a transparent computational mechanism linking collective intelligence with O-ring production and identifies boundary conditions under which high-CPS teams can still be limited by weak links and interdependence.
Peer reviewed STiMUS-HAI: A Stigmergic–Mutualistic Agent-Based Model of Human-AI Collaboration on Shared Digital Artefacts
Yevgeny Patarakin | Published Monday, July 13, 2026 | Last modified Thursday, August 20, 2026STiMUS-HAI (Stigmergic–Mutualistic IMOI Model, Human-AI extension) is an agent-based model of teamwork in socio-technical systems where human and AI contributors collaborate through shared digital artefacts — wiki pages, code files, issue tickets, project cards, Scratch projects — represented as patches in a NetLogo world. It extends the human-only base model STiMUS v2.2, which established that two coordination mechanisms — stigmergy (indirect coordination through traces left in the environment) and mutualism (mutual benefit between contributors and the artefacts they tend) — can be decoupled: stigmergy decides where a contributor works, mutualism decides with what effort. STiMUS-HAI preserves this decoupling unchanged and adds two further theoretical questions: whether mixing AI agents into a human team distorts human coordination in ways that aggregate indicators hide, and whether AI’s cost to team outcomes depends on the type of work AI performs, not only on how much of it is present.
Two breeds of turtle — humans and ai-agents — follow identical target-selection, pheromone, and mutualism rules, so that any behavioural difference is attributable to team composition rather than a built-in advantage. The one designed asymmetry: AI agents never accumulate shared-mental-model and their motivation is fixed rather than adaptive. On top of this v3.0 baseline, v3.1 adds a task-type dimension to artefacts (“prediction” versus “judgment”, set via a judgment-share slider) that scales down AI edit-power specifically on judgment-requiring artefacts, and an ai-trust mechanic: humans build or lose trust in AI contributions based on the population-relative percentile rank of observed AI work quality (bottom-quartile work counts as an observed “error”), and that trust gates how much mutualistic benefit a human derives from continuing an AI’s work. Trust erodes quickly on a single error and recovers only after a streak of confirmed successes — an intentional asymmetry.
Peer reviewed STiMUS: A Stigmergic–Mutualistic Agent-Based Model of Teamwork on Shared Digital Artefacts (IMOI)
Yevgeny Patarakin | Published Friday, July 03, 2026 | Last modified Wednesday, July 22, 2026STiMUS (Stigmergic–Mutualistic IMOI Model) is an agent-based model of teamwork in socio-technical systems where contributors collaborate through shared digital artefacts — wiki pages, code files, issue tickets, project cards, Scratch projects — represented as patches in a NetLogo world. The model integrates two coordination mechanisms. Stigmergy is indirect coordination through traces left in a shared environment: each edit deposits a pheromone that diffuses to neighbouring patches and evaporates over time, so recent activity attracts further contributions. Mutualism is a reciprocal benefit loop in which valuable, well-maintained artefacts raise contributor motivation and shared understanding, while motivated contributors improve artefacts.
Contributors (turtles of the contributor breed) carry individual state: skill, motivation, shared-mental-model, specialty, benefit-gain, and an explicit-mode flag. At each tick every contributor selects a target artefact with an ant-colony-optimization-style rule weighing the artefact’s pheromone, incompleteness (1 - completeness), resource-value, and topic match between specialty and the artefact’s topic-tag; with probability p-explicit it instead takes the patch with the highest maintenance-need, modelling explicit task assignment. Each edit increases pheromone, quality, completeness and reuse-count, raises resource-value, lowers maintenance-need, and appends the editor to the artefact’s edit-authors list. When the previous last-editor-id differs from the current editor, the Edit Succession Ratio rises, the editor’s shared-mental-model grows, and a co-editing link is created — operationalising the idea that repeated cross-author succession on the same artefact builds shared understanding. Contributors’ motivation is updated from the benefit drawn from the visited artefact.
Each patch maintains a stigmergic layer (pheromone, quality, completeness, recentness, last-editor-id, edit-count, edit-authors) and a mutualistic layer (resource-value, reuse-count, maintenance-need, topic-tag), plus task flags (is-task?, task-complexity). Global monitors report the Edit Succession Ratio (ESR = cross-author-edits / total-edits, and an alternative esr-value = share of edited patches with more than one distinct author), mean-quality, mean-resource-value, a mutualism-index averaging contributor benefit and resource value, coediting-density (network density of the co-editing graph), active-pages-share, and task-completion-rate. The model logs every edit as a bipartite edge (tick, author_id, pageid, specialty, topic_tag, quality), exportable to CSV.
…
Zensei Wago: A Wealth-Integrated Social Capital Model
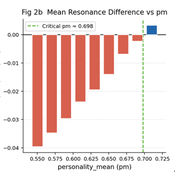
hiiki | Published Friday, May 15, 2026Interest-based compound economies generate monotonically increasing wealth inequality through multiplicative accumulation dynamics, yet the conditions under which gift-based reciprocal exchange outperforms such systems in collective well-being remain unquantified. We present Zensei Wago (全生和合), a seven-layer agent-based model comparing a Gift Resource Circulation (GRC) economy with a Compound Interest Circulation (CIC) economy under identical initial conditions. Across N = 5000 Monte Carlo replications (T = 700 ticks, N = 100 agents), GRC produced significantly higher collective resonance than CIC (p < 0.001, Cohen’s d = +0.171), above a critical prosocial threshold pm ≈ 0.698. Cohen’s d grows monotonically with duration — d = +1.943 at T = 1500 and d = +4.126 at T = 3000 — driven primarily by structural collapse of CIC resonance as inequality exceeds a critical Gini threshold (G > 0.333), while GRC resonance remains stable. The gift mechanism further decouples collective well-being from distributional outcomes, generating resonance through relational quality rather than material redistribution. Network topology analysis across seven configurations — combining a Watts-Strogatz rewiring sweep and a T = 1500 longitudinal replication — reveals that ring topology maximises GRC advantage (d = +1.17), that most topology-dependent reversals are transient (sparse and small-world both transition to significantly positive by T = 1500), and that a critical rewiring threshold of p ≈ 0.10–0.20 separates GRC-advantaged from GRC-disadvantaged network configurations. Scale-free networks remain persistently adverse (d = -7.24*), requiring structural redesign for gift-economy viability.
Forest Logging and Ecosystem Degradation
Carla Guerrero | Published Sunday, February 15, 2026This model simulates a forest ecosystem affected by human logging. We explore different kind of approaches and their possible consequences for the ecosystem. Loggers can either be responsible or irresponsible, they will either take care to cut trees or not. In turn their actions will have consequences on the quality of the soil, the atmosphere as well as their profit made from logging. In this model we see that even careful management cannot prevent the degradation of the forest ecosystem.
LogoClim: WorldClim in NetLogo
Daniel Vartanian Leandro Garcia Aline Aline Martins de Carvalho | Published Thursday, July 03, 2025 | Last modified Monday, July 13, 2026LogoClim is a NetLogo model designed to be integrated into other simulations through the LevelSpace extension (Hjorth et al., 2020), providing high resolution climate data from sources validated and used by the Intergovernmental Panel on Climate Change (IPCC).
The model simplifies and standardizes the integration of climate data into NetLogo, allowing researchers to focus their efforts on the model itself with the assurance of using reliable and widely recognized data. Although its main use is as a component of larger simulations, LogoClim also has its own graphical interface for monitoring and checking the datasets.
The climate data comes from the WorldClim 2.1 project (Fick & Hijmans, 2017), for which LogoClim works as an interface to NetLogo. The model supports all three WorldClim data series: (1) Historical Climate Data (1970 to 2000), with 12 monthly points for minimum, mean, and maximum temperature, precipitation, solar radiation, wind speed, vapor pressure, elevation, and bioclimatic variables; (2) Historical Monthly Weather Data (1951 to 2024), based on downscaling of CRU-TS-4.09, developed by the Climatic Research Unit at the University of East Anglia (Harris et al., 2020), with minimum and maximum temperature and total precipitation; and (3) Future Climate Data, based on downscaling climate projections derived from global climate models of the Coupled Model Intercomparison Project Phase 6 (CMIP6) (Eyring et al., 2016) for four future periods (2021 to 2040, 2041 to 2060, 2061 to 2080, and 2081 to 2100) and four scenarios based on the Shared Socioeconomic Pathways (SSPs 126, 245, 370, and 585), covering minimum and maximum temperature, total precipitation, and bioclimatic variables. All series are available at multiple spatial resolutions, from 10 minutes (about 340 km² at the equator) to 30 seconds (about 1 km² at the equator).
…
Displaying 10 of 55 results quality clear search