Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 139 results for "Nathan Ryan" clear search
Gender differentiation model
Sylvie Huet | Published Monday, April 20, 2020 | Last modified Thursday, April 23, 2020This is a gender differentiation model in terms of reputations, prestige and self-esteem (presented in the paper https://journals.plos.org/plosone/article?id=10.1371/journal.pone.0236840). The model is based on the influence function of the Leviathan model (Deffuant, Carletti, Huet 2013 and Huet and Deffuant 2017) considering two groups.
This agent-based model studies how inequalities can be explained by the difference of open-mindness between two groups of interacting agents. We consider agents having an opinion/esteem about each other and about themselves. During dyadic meetings, agents change their respective opinion about each other and possibly about other agents they gossip about, with a noisy perception of the opinions of their interlocutor. Highly valued agents are more influential in such encounters. We study an heterogeneous population of two different groups: one more open to influence of others, taking less into account their perceived difference of esteem, called L; a second one less prone to it, called S, who designed the credibility they give to others strongly based on how higher or lower valued than themselves they perceive them.
We show that a mixed population always turns in favor to some agents belonging to the group of less open-minded agents S, and harms the other group: (1) the average group self-opinion or reputation of S is always better than the one of L; (2) the higher rank in terms of reputation are more frequently occupied by the S agents while the L agents occupy more the bottom rank; (3) the properties of the dynamics of differentiation between the two groups are similar to the properties of the glass ceiling effect proposed by Cotter et al (2001).
Anchored logistic agent-based model of cooperation among fourteen European Union member states, with structural diagnostics
Alessandro Brugnoletti | Published Friday, October 02, 2026An agent-based model in which fourteen European Union member states each carry a cooperation
propensity in [0,1], updated by a logistic link applied to a latent index that combines the unit’s
own previous state, a weighted average of the other units’ states, and four min-max normalised
exogenous indicators (cooperative benefit, opportunistic temptation, systemic exit cost,
intertemporal confidence). The logistic centres are anchored so that the observed 2024
configuration is an exact fixed point of the baseline map, the device that makes such models
…
Evolutionary Prosocial Behavior Algorithm 1.1 (EPBA_1.1)
Andrea Ceschi | Published Tuesday, September 04, 2018In order to test how prosocial strategies (compassionate altruism vs. reciprocity) grow over time, we developed an evolutionary simulation model where artificial agents are equipped with different emotionally-based drivers that vary in strength. Evolutionary algorithms mimic the evolutionary selection process by letting the chances of agents conceiving offspring depend on their fitness. Equipping the agents with heritable prosocial strategies allows for a selection of those strategies that result in the highest fitness. Since some prosocial attributes may be more successful than others, an initially heterogeneous population can specialize towards altruism or reciprocity. The success of particular prosocial strategies is also expected to depend on the cultural norms and environmental conditions the agents live in.
Genetic Algorithm and Food Choice
Diego Martín Díaz Córdova | Published Monday, August 10, 2026This models simulate how people choose their food buyings based on a limited budget and a food quality index. In order to make the choice the agents call a genetic algorithm who optimizes the buying. The agents are distributed randomly and there are 5 store options where agents can buy meat, fruits and vegetables, bread, ultraprocessed and medications. Agents need all of them, each of one has a different price and a different quality index. The genetic algorithm perform an optimization procedure in order to clasiffy what food set is the best for each agent. The agents are coloured based on their budget if the’ve got less than 100, then they are pink otherwise they are white.
WaterScape
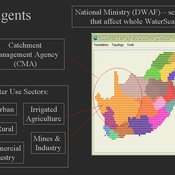
Erin Bohensky | Published Monday, February 06, 2012 | Last modified Saturday, April 27, 2013The WaterScape is an agent-based model of the South African water sector. This version of the model focuses on potential barriers to learning in water management that arise from interactions between human perceptions and social-ecological system conditions.
A Complex Model of Voter Turnout
Bruce Edmonds Laurence Lessard-Phillips Ed Fieldhouse | Published Monday, October 13, 2014 | Last modified Tuesday, August 18, 2015This is a complex “Data Integration Model”, following a “KIDS” rather than a “KISS” methodology - guided by the available evidence. It looks at the complex mix of social processes that may determine why people vote or not.
Homophily-driven Network Evolution and Diffusion
Mustafa Yavaş Gönenç Yücel | Published Thursday, January 08, 2015The model is an experimental ground to study the impact of network structure on diffusion. It allows to construct a social network that already has some measurable level of homophily, and simulate a diffusion process over this social network.
Contract farming in the Mekong Delta's rice supply chain
Hung Nguyen | Published Tuesday, February 05, 2019We study three obstacles of the expansion of contract rice farming in the Mekong Delta (MKD) region. The failure of buyers in building trust-based relationship with small-holder farmers, unattractive offered prices from the contract farming scheme, and limited rice processing capacity have constrained contractors from participating in the large-scale paddy field program. We present an agent-based model to examine the viability of contract farming in the region from the contractor perspective.
The model focuses on financial incentives and trust, which affect the decision of relevant parties on whether to participate and honor a contract. The model is also designed in the context of the MKD’s rice supply chain with two contractors engaging in the contract rice farming scheme alongside an open market, in which both parties can renege on the agreement. We then evaluate the contractors’ performances with different combinations of scenarios related to the three obstacles.
Our results firstly show that a fully-equipped contractor who opportunistically exploits a relatively small proportion (less than 10%) of the contracted farmers in most instances can outperform spot market-based contractors in terms of average profit achieved for each crop. Secondly, a committed contractor who offers lower purchasing prices than the most typical rate can obtain better earnings per ton of rice as well as higher profit per crop. However, those contractors in both cases could not enlarge their contract farming scheme, since either farmers’ trust toward them decreases gradually or their offers are unable to compete with the benefits from a competitor or the spot market. Thirdly, the results are also in agreement with the existing literature that the contract farming scheme is not a cost-effective method for buyers with limited rice processing capacity, which is a common situation among the contractors in the MKD region.
ABM for Underwater optical wireless communication in a water tank
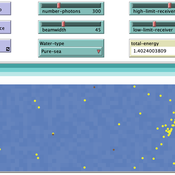
Mohamed ABID | Published Sunday, May 29, 2022This model simulates the propagation of photons in a water tank. A source of light emits an impulse of photons with equal energy represented by yellow dots. These photons are then scattered by water particles before possibly reaching the photo-detector represented by a gray line. Different types of water are considered. For each one of them we calculate the total received energy.
The water tank is represented by a blue rectangle with fixed dimensions. It’s exposed to the air interface and has totally absorbent barriers. Four types of water are supported. Each one is characterized by its absorption and scattering coefficients.
At the source, the photons are generated uniformly with a random direction within the beamwidth. Each photon travels a random distance drawn from a distribution depending on the water characteristics before encountering a water particle.
Based on the updated position of the photon, three situations may occur:
-The photon hits the barrier of the tank on its trajectory. In this case it’s considered as lost since the barriers are assumed totally absorbent.
…
Peer reviewed STiMUS-HAI: A Stigmergic–Mutualistic Agent-Based Model of Human-AI Collaboration on Shared Digital Artefacts
Yevgeny Patarakin | Published Monday, July 13, 2026 | Last modified Thursday, August 20, 2026STiMUS-HAI (Stigmergic–Mutualistic IMOI Model, Human-AI extension) is an agent-based model of teamwork in socio-technical systems where human and AI contributors collaborate through shared digital artefacts — wiki pages, code files, issue tickets, project cards, Scratch projects — represented as patches in a NetLogo world. It extends the human-only base model STiMUS v2.2, which established that two coordination mechanisms — stigmergy (indirect coordination through traces left in the environment) and mutualism (mutual benefit between contributors and the artefacts they tend) — can be decoupled: stigmergy decides where a contributor works, mutualism decides with what effort. STiMUS-HAI preserves this decoupling unchanged and adds two further theoretical questions: whether mixing AI agents into a human team distorts human coordination in ways that aggregate indicators hide, and whether AI’s cost to team outcomes depends on the type of work AI performs, not only on how much of it is present.
Two breeds of turtle — humans and ai-agents — follow identical target-selection, pheromone, and mutualism rules, so that any behavioural difference is attributable to team composition rather than a built-in advantage. The one designed asymmetry: AI agents never accumulate shared-mental-model and their motivation is fixed rather than adaptive. On top of this v3.0 baseline, v3.1 adds a task-type dimension to artefacts (“prediction” versus “judgment”, set via a judgment-share slider) that scales down AI edit-power specifically on judgment-requiring artefacts, and an ai-trust mechanic: humans build or lose trust in AI contributions based on the population-relative percentile rank of observed AI work quality (bottom-quartile work counts as an observed “error”), and that trust gates how much mutualistic benefit a human derives from continuing an AI’s work. Trust erodes quickly on a single error and recovers only after a streak of confirmed successes — an intentional asymmetry.
Displaying 10 of 139 results for "Nathan Ryan" clear search