Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 283 results for "Ala Jlif" clear search
Knowledge Based Economy
Guido Fioretti Sirio Capizzi Ruggero Rossi Martina Casari Ala Jlif | Published Tuesday, May 18, 2021Knowledge Based Economy (KBE) is an artificial economy where firms placed in geographical space develop original knowledge, imitate one another and eventually recombine pieces of knowledge. In KBE, consumer value arises from the capability of certain pieces of knowledge to bridge between existing items (e.g., Steve Jobs illustrated the first smartphone explaining that you could make a call with it, but also listen to music and navigate the Internet). Since KBE includes a mechanism for the generation of value, it works without utility functions and does not need to model market exchanges.
Peer reviewed ana-wag
Nils Ferrand Géraldine Abrami Mamadou Diallo Wanda Aquae Gaudi Stefano Farolfi Bruno Bonté | Published Monday, February 13, 2017 | Last modified Friday, May 10, 2019The ana-wag model, for Analyse Wat-A-Game (WAG), is a NetLogo version of the WAG role playing game. It enables to model a river catchment with the graphical modelling language WAG and to play it as a network-game (each player is a water user).
The fourth and final extension to the standard Adder model to replicate the various interventions typically associated with Transition Experiments.
“Food for all” (FFD)
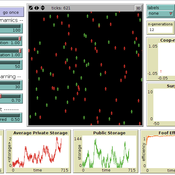
José Manuel Galán Andreas Angourakis Andrea L Balbo José Santos | Published Friday, April 25, 2014 | Last modified Monday, April 08, 2019“Food for all” (FFD) is an agent-based model designed to study the evolution of cooperation for food storage. Households face the social dilemma of whether to store food in a corporate stock or to keep it in a private stock.
Enhancing recycling of construction materials; an agent based model with empirically based decision parameters
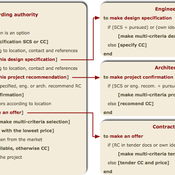
Christof Knoeri Igor Nikolic Hans-Joerg Althaus Claudia Binder | Published Sunday, October 21, 2012 | Last modified Monday, June 09, 2014This model allows for analyzing the most efficient levers for enhancing the use of recycled construction materials, and the role of empirically based decision parameters.
This model extends the original Artifical Anasazi (AA) model to include individual agents, who vary in age and sex, and are aggregated into households. This allows more realistic simulations of population dynamics within the Long House Valley of Arizona from AD 800 to 1350 than are possible in the original model. The parts of this model that are directly derived from the AA model are based on Janssen’s 1999 Netlogo implementation of the model; the code for all extensions and adaptations in the model described here (the Artificial Long House Valley (ALHV) model) have been written by the authors. The AA model included only ideal and homogeneous “individuals” who do not participate in the population processes (e.g., birth and death)–these processes were assumed to act on entire households only. The ALHV model incorporates actual individual agents and all demographic processes affect these individuals. Individuals are aggregated into households that participate in annual agricultural and demographic cycles. Thus, the ALHV model is a combination of individual processes (birth and death) and household-level processes (e.g., finding suitable agriculture plots).
As is the case for the AA model, the ALHV model makes use of detailed archaeological and paleoenvironmental data from the Long House Valley and the adjacent areas in Arizona. It also uses the same methods as the original model (from Janssen’s Netlogo implementation) to estimate annual maize productivity of various agricultural zones within the valley. These estimates are used to determine suitable locations for households and farms during each year of the simulation.
Vacunación-Covid Ecuador
Adrian Lara | Published Tuesday, March 22, 2022El modelo a continuación, fue desarrollado para el DATA CHALLENGE 2022. Es un análisis de la información descargada del Portal de datos abiertos de Ecuador. Dentro del modelo podemos realizar una breve exploración de la información así como una simulación respecto al proceso de vacunación en Ecuador.
When Contact Backfires, and When It Does Not: A Computational Model of the Opinion Dynamics of Intergroup Attitudes
Yade Rotte Andreas Flache Alla Loseva | Published Wednesday, October 14, 2026This model represents individuals from two different groups interacting and sharing attitudes toward both groups. Through these interactions, individuals adjust their attitudes, which can lead to different outcomes in opinion dynamics. The model can study both intra-group and inter-group opinion dynamics. Under certain conditions, agents with initially moderate attitudes might enter a negative spiral, leading to increasingly extreme intergroup attitudes. Alternatively, these moderate attitudes can foster consensus between groups, resulting in agreement on intergroup attitudes. This model serves as a tool for exploring opinion polarization, particularly in contexts where attitudes evolve through interaction rather than remaining static.
By adjusting different parameters, one can examine the effects of variations in attitude distributions; group size and relative group size; contributions of xenophobia, opinion distance, and individual attitudes towards the outgroup; as well as ratio between xenophobia and attitudinal bias to the overall intergroup bias.
The model accompanies the paper When contact backfires, and when it does not: A computational model of the opinion dynamics of intergroup attitudes.
Peer reviewed Integrating Reinforcement Learning in Agent-Based Modeling for Dynamic Investment Decisions
Muhammad Khurram Ali Haider Ali Hafiz Mohammad | Published Tuesday, May 05, 2026This model is a part of an ongoing research project on Multiagent Reinforcement Learning (MARL). The ODD protocol is included in the model. In this version of the model, Proximal Policy Optimization (PPO) is designed in the agent behaviors. It also includes a designed experiment in its Behavior Space which is used in the Response Surface Methodology and training of an Artificial Neural Network (ANN) based Recommender System.
Peer reviewed Gradient Descent Simulation
Ilyes Azouani | Published Wednesday, March 18, 2026 | Last modified Monday, May 25, 2026This model visualizes gradient descent optimization - the fundamental algorithm used to train neural networks and other machine learning models. Agents represent different optimization algorithms searching for the minimum of a loss landscape (the “error surface” that ML models try to minimize during training).
The model demonstrates how different optimizer types (SGD, Momentum with different parameters) behave on various loss landscapes, from simple bowls to the notoriously difficult Rosenbrock “banana valley” function. This helps build intuition about why certain optimization algorithms work better than others for different problem geometries.
HOW IT WORKS
…
Displaying 10 of 283 results for "Ala Jlif" clear search