Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 9 of 59 results for "Gil Gambash" clear search
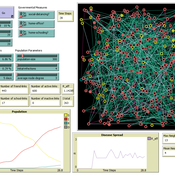
The Effect of Different Governmental Pandemic Control Measures on the Spread of a Virus Disease
Chiara Letter | Published Wednesday, January 26, 2022In this model, the spread of a virus disease in a network consisting of school pupils, employed, and umemployed people is simulated. The special feature in this model is the distinction between different types of links: family-, friends-, school-, or work-links. In this way, different governmental measures can be implemented in order to decelerate or stop the transmission.
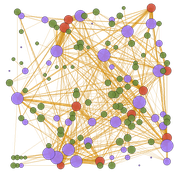
Peer reviewed TRANSOPE: a multi-agent model to simulate outsourcing networks in road freight transport.
Aitor Salas-Peña Blanca Rosa Cases Gutiérrez | Published Friday, October 21, 2022A road freight transport (RFT) operation involves the participation of several types of companies in its execution. The TRANSOPE model simulates the subcontracting process between 3 types of companies: Freight Forwarders (FF), Transport Companies (TC) and self-employed carriers (CA). These companies (agents) form transport outsourcing chains (TOCs) by making decisions based on supplier selection criteria and transaction acceptance criteria. Through their participation in TOCs, companies are able to learn and exchange information, so that knowledge becomes another important factor in new collaborations. The model can replicate multiple subcontracting situations at a local and regional geographic level.
The succession of n operations over d days provides two types of results: 1) Social Complex Networks, and 2) Spatial knowledge accumulation environments. The combination of these results is used to identify the emergence of new logistics clusters. The types of actors involved as well as the variables and parameters used have their justification in a survey of transport experts and in the existing literature on the subject.
As a result of a preferential selection process, the distribution of activity among agents shows to be highly uneven. The cumulative network resulting from the self-organisation of the system suggests a structure similar to scale-free networks (Albert & Barabási, 2001). In this sense, new agents join the network according to the needs of the market. Similarly, the network of preferential relationships persists over time. Here, knowledge transfer plays a key role in the assignment of central connector roles, whose participation in the outsourcing network is even more decisive in situations of scarcity of transport contracts.
Introducing two extensions of Schelling's segregation model
Andreas Flache Carlos A. de Matos Fernandes | Published Monday, January 25, 2021Schelling famously proposed an extremely simple but highly illustrative social mechanism to understand how strong ethnic segregation could arise in a world where individuals do not necessarily want it. Schelling’s simple computational model is the starting point for our extensions in which we build upon Wilensky’s original NetLogo implementation of this model. Our two NetLogo models can be best studied while reading our chapter “Agent-based Computational Models” (Flache and de Matos Fernandes, 2021). In the chapter, we propose 10 best practices to elucidate how agent-based models are a unique method for providing and analyzing formally precise, and empirically plausible mechanistic explanations of puzzling social phenomena, such as segregation, in the social world. Our chapter addresses in particular analytical sociologists who are new to ABMs.
In the first model (SegregationExtended), we build on Wilensky’s implementation of Schelling’s model which is available in NetLogo library (Wilensky, 1997). We considerably extend this model, allowing in particular to include larger neighborhoods and a population with four groups roughly resembling the ethnic composition of a contemporary large U.S. city. Further features added concern the possibility to include random noise, and the addition of a number of new outcome measures tuned to highlight macro-level implications of the segregation dynamics for different groups in the agent society.
In SegregationDiscreteChoice, we further modify the model incorporating in particular three new features: 1) heterogeneous preferences roughly based on empirical research categorizing agents into low, medium, and highly tolerant within each of the ethnic subgroups of the population, 2) we drop global thresholds (%-similar-wanted) and introduce instead a continuous individual-level single-peaked preference function for agents’ ideal neighborhood composition, and 3) we use a discrete choice model according to which agents probabilistically decide whether to move to a vacant spot or stay in the current spot by comparing the attractiveness of both locations based on the individual preference functions.
…
Exploring Urban Shrinkage
Andrew Crooks | Published Thursday, March 19, 2020While the world’s total urban population continues to grow, this growth is not equal. Some cities are declining, resulting in urban shrinkage which is now a global phenomenon. Many problems emerge due to urban shrinkage including population loss, economic depression, vacant properties and the contraction of housing markets. To explore this issue, this paper presents an agent-based model stylized on spatially explicit data of Detroit Tri-county area, an area witnessing urban shrinkage. Specifically, the model examines how micro-level housing trades impact urban shrinkage by capturing interactions between sellers and buyers within different sub-housing markets. The stylized model results highlight not only how we can simulate housing transactions but the aggregate market conditions relating to urban shrinkage (i.e., the contraction of housing markets). To this end, the paper demonstrates the potential of simulation to explore urban shrinkage and potentially offers a means to test polices to alleviate this issue.
Geospatial Agent-Based Model of Immigrant Settlement Dynamics in Metro Vancouver
Liliana Perez Maryam Yousefi Navid Mahdizadeh Gharakhanlou | Published Wednesday, December 03, 2025This agent-based model simulates how new immigrant households choose where to live in Metro Vancouver under the origins diversity scenario. The model begins with 16,000 household agents, reflecting an expected annual population increase of about 42,500 people based on an average household size of 2.56. Each agent is assigned four characteristics: one of ten origin categories, income level (adjusted using NOC data and recent immigrant earnings), likelihood of having children, and preferred mode of commuting. The ten origin groups are drawn from Census patterns, including six subgroups within the broader Asian category (China, India, the Philippines, Iran, South Korea, and Other Asian countries) and two categories for immigrants from the Americas. This refined classification better captures the diversity of newcomers arriving in the region.
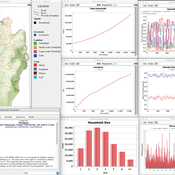
OMOLAND-CA: An Agent-Based Modeling of Rural Households’ Adaptation to Climate Change
Atesmachew Hailegiorgis Claudio Cioffi-Revilla Andrew Crooks | Published Tuesday, July 25, 2017 | Last modified Tuesday, July 10, 2018The purpose of the OMOLAND-CA is to investigate the adaptive capacity of rural households in the South Omo zone of Ethiopia with respect to variation in climate, socioeconomic factors, and land-use at the local level.
Artificial Anasazi: Baseline Fixes, Dynamic Soil and Plot Crowding
Thomas Tuoti | Published Sunday, October 04, 2026Artificial Anasazi is an agent-based model of farming households in the Long House Valley, Arizona, from 800 to 1350 CE. Each household chooses where to farm and settle based on expected harvest, water sources and stored maize, and simulated household counts are compared with the archaeological record.
This release adapts the NetLogo Models Library version (Stonedahl & Wilensky 2010) of Janssen’s (2009) NetLogo replication of the original Ascape model (Dean et al. 2000; Axtell et al. 2002). It contains four configurations in one NetLogo 7.0.4 file, selected with two switches:
- Both switches off: the baseline, which is the Models Library model with small fixes that make it work as intended (the arable-uplands zone name, the setup base yield, the initial household count, one-tick-lag capacity reporting, and seed control with observation-only instruments).
soil-on?: dynamic soil quality that depletes under cultivation and regrows, following Janssen (2010, eq. 4).
…
Agent-Based Simulation of Operational and Fare Integration in Multi-Operator Bus Networks: Institutional Trade-offs and Robustness Analysis
Lorenzo Ros-McDonnell María Victoria de-la-Fuente-Aragon Salvador Martinez-Artero-Martinez Khaoula El Bied | Published Tuesday, November 03, 2026This study separates operational interoperability, fare integration and revenue-sharing governance in a stylised multi-operator bus network. An agent-based model implemented in NetLogo 7.0.3 represents passengers, buses and stations across 14 stations, nine routes and three operators. A 2 × 2 institutional design is complemented by financial clearing comparisons and 43,200 robustness runs: behavioural sensitivity (E1), a 243-configuration operational factorial (E2), and targeted joint behavioural–operational stress testing (E3). The audited experiment records show favourable interoperability effects on waiting, total travel time, transfers and realised generalised cost in all 1,944 E2 and 768 E3 configuration-level primary comparisons. Fare integration substantially reduces passenger expenditure but produces an aggregate deficit under the assumed accounting coefficients. Revenue-sharing rules redistribute operator-level outcomes without changing aggregate profit or passenger trajectories by construction. The model is intended to identify mechanisms and test conditional robustness, not predict city-specific policy effects. The paper contributes an explicit separation of access, pricing and settlement mechanisms coupled with reproducible factorial and stress-test comparisons.
Artificial Long House Valley-Black Mesa
Amy Warren Lisa Sattenspiel | Published Thursday, March 19, 2020This model is an extension of the Artificial Long House Valley (ALHV) model developed by the authors (Swedlund et al. 2016; Warren and Sattenspiel 2020). The ALHV model simulates the population dynamics of individuals within the Long House Valley of Arizona from AD 800 to 1350. Individuals are aggregated into households that participate in annual agricultural and demographic cycles. The present version of the model incorporates features of the ALHV model including realistic age-specific fertility and mortality and, in addition, it adds the Black Mesa environment and population, as well as additional methods to allow migration between the two regions.
As is the case for previous versions of the ALHV model as well as the Artificial Anasazi (AA) model from which the ALHV model was derived (Axtell et al. 2002; Janssen 2009), this version makes use of detailed archaeological and paleoenvironmental data from the Long House Valley and the adjacent areas in Arizona. It also uses the same methods as the original AA model to estimate annual maize productivity of various agricultural zones within the Long House Valley. A new environment and associated methods have been developed for Black Mesa. Productivity estimates from both regions are used to determine suitable locations for households and farms during each year of the simulation.
Displaying 9 of 59 results for "Gil Gambash" clear search