Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 378 results for "Daniel J Singer" clear search
Hybrid agent-based methodology for testing response protocols
Fernando Sancho Caparrini | Published Wednesday, February 03, 2021In recent years we have seen multiple incidents with a large number of people injured and killed by one or more armed attackers. Since this type of violence is difficult to predict, detecting threats as early as possible allows to generate early warnings and reduce response time. In this context, any tool to check and compare different action protocols can be a further step in the direction of saving lives. Our proposal combines features from continuous and discrete models to obtain the best of both worlds in order to simulate large and crowded spaces where complex behavior individuals interact. With this proposal we aim to provide a tool for testing different security protocols under several emergency scenarios, where spaces, hazards, and population can be customized. Finally, we use a proof of concept implementation of this model to test specific security protocols under emergency situations for real spaces. Specifically, we test how providing some users of a university college with an app that informs about the type and characteristics of the ongoing hazard, affects in the safety performance.
Evolutionary Model of Subculture Choice
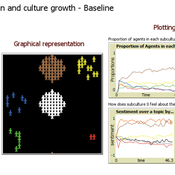
Diogo Alves | Published Monday, December 19, 2022This is an original model of (sub)culture diffusion.
It features a set of agents (dubbed “partygoers”) organized initially in clusters, having properties such as age and a chromosome of opinions about 6 different topics. The partygoers interact with a set of cultures (also having a set of opinions subsuming those of its members), in the sense of refractory or unhappy members of each setting about to find a new culture and trading information encoded in the genetic string (originally encoded as -1, 0, and 1, resp. a negative, neutral, and positive opinion about each of the 6 traits/aspects, e.g. the use of recreational drugs). There are 5 subcultures that both influence (through the aforementioned genetic operations of mutation and recombination of chromosomes simulating exchange of opinions) and are influenced by its members (since a group is a weighted average of the opinions and actions of its constituents). The objective of this feedback loop is to investigate under which conditions certain subculture sizes emerge, but the model is open to many other kinds of explorations as well.
The Informational Assumptions of Schelling Segregation: An Agent-Based Decomposition of Cue Inference, Cultural Schemas, and Residential Sorting
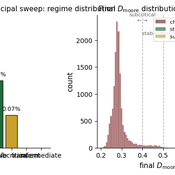
Eric Gladstone | Published Wednesday, May 13, 2026This computational model accompanies the article “The Informational Assumptions of Schelling Segregation: An Agent-Based Decomposition of Cue Inference, Cultural Schemas, and Residential Sorting.” It implements an agent-based model in which agents infer latent neighborhood-type classes from noisy non-demographic cues through schema-specific diagnostic mappings, update beliefs, and relocate when satisfaction on a preferred latent class falls below a threshold.
The model serves as a mechanism-isolation device for studying the informational architecture underlying Schelling-style residential sorting. It includes the principal sweep configuration (14,400 runs across a seven-parameter grid), a disagreement-metric sub-sweep with permutation-minimized Jensen-Shannon divergence recorded natively, controls (positive, negative, and frozen-belief), a paired-seed cue-channel perturbation experiment, and selected-cell sensitivity sweeps for cue persistence and home-biased mobility.
The full ODD protocol, parameter manifests, deterministic seed schedules, processed outputs, regenerable figure scripts, the verification test suite, and the satisfaction-mapping audit document are included. Every reported run is deterministic given a (config, seed) pair, and an included audit script verifies bit-for-bit replay on sampled runs.
LogoClim: WorldClim in NetLogo
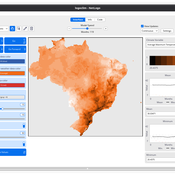
Daniel Vartanian Leandro Garcia Aline Martins de Carvalho Aline | Published Thursday, July 03, 2025 | Last modified Monday, July 13, 2026LogoClim is a NetLogo model designed to be integrated into other simulations through the LevelSpace extension (Hjorth et al., 2020), providing high resolution climate data from sources validated and used by the Intergovernmental Panel on Climate Change (IPCC).
The model simplifies and standardizes the integration of climate data into NetLogo, allowing researchers to focus their efforts on the model itself with the assurance of using reliable and widely recognized data. Although its main use is as a component of larger simulations, LogoClim also has its own graphical interface for monitoring and checking the datasets.
The climate data comes from the WorldClim 2.1 project (Fick & Hijmans, 2017), for which LogoClim works as an interface to NetLogo. The model supports all three WorldClim data series: (1) Historical Climate Data (1970 to 2000), with 12 monthly points for minimum, mean, and maximum temperature, precipitation, solar radiation, wind speed, vapor pressure, elevation, and bioclimatic variables; (2) Historical Monthly Weather Data (1951 to 2024), based on downscaling of CRU-TS-4.09, developed by the Climatic Research Unit at the University of East Anglia (Harris et al., 2020), with minimum and maximum temperature and total precipitation; and (3) Future Climate Data, based on downscaling climate projections derived from global climate models of the Coupled Model Intercomparison Project Phase 6 (CMIP6) (Eyring et al., 2016) for four future periods (2021 to 2040, 2041 to 2060, 2061 to 2080, and 2081 to 2100) and four scenarios based on the Shared Socioeconomic Pathways (SSPs 126, 245, 370, and 585), covering minimum and maximum temperature, total precipitation, and bioclimatic variables. All series are available at multiple spatial resolutions, from 10 minutes (about 340 km² at the equator) to 30 seconds (about 1 km² at the equator).
…
Food Safety Inspection Model - Random Strategy
Sara Mcphee-Knowles | Published Wednesday, March 05, 2014 | Last modified Monday, April 08, 2019The Inspection Model represents a basic food safety system where inspectors, consumers and stores interact. The purpose of the model is to provide insight into an optimal level of inspectors in a food system by comparing three search strategies.
Food Safety Inspection Model - Stores Signal with Errors
Sara Mcphee-Knowles | Published Wednesday, March 05, 2014 | Last modified Monday, April 08, 2019The Inspection Model represents a basic food safety system where inspectors, consumers and stores interact. The purpose of the model is to provide insight into an optimal level of inspectors in a food system by comparing three search strategies.
Food Safety Inspection Model - Stores Signal
Sara Mcphee-Knowles | Published Wednesday, March 05, 2014 | Last modified Monday, August 26, 2019The Inspection Model represents a basic food safety system where inspectors, consumers and stores interact. The purpose of the model is to provide insight into an optimal level of inspectors in a food system by comparing three search strategies.
(De-)Stabilising effect of diffusions
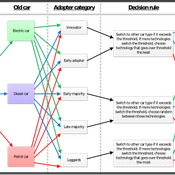
Julia Kasmire Bert Van Meeuwen Cornelis Eikelboom | Published Tuesday, August 11, 2015What is stable: the large but coordinated change during a diffusion or the small but constant and uncoordinated changes during a dynamic equilibrium? This agent-based model of a diffusion creates output that reveal insights for system stability.
Peer reviewed Gregarious Behavior, Human Colonization and Social Differentiation Agent-Based Model
Gert Jan Hofstede Mark R Kramer Sebastian Fajardo Andrés Bernal Martijn de Vries | Published Thursday, August 20, 2020 | Last modified Thursday, October 29, 2020Studies of colonization processes in past human societies often use a standard population model in which population is represented as a single quantity. Real populations in these processes, however, are structured with internal classes or stages, and classes are sometimes created based on social differentiation. In this present work, information about the colonization of old Providence Island was used to create an agent-based model of the colonization process in a heterogeneous environment for a population with social differentiation. Agents were socially divided into two classes and modeled with dissimilar spatial clustering preferences. The model and simulations assessed the importance of gregarious behavior for colonization processes conducted in heterogeneous environments by socially-differentiated populations. Results suggest that in these conditions, the colonization process starts with an agent cluster in the largest and most suitable area. The spatial distribution of agents maintained a tendency toward randomness as simulation time increased, even when gregariousness values increased. The most conspicuous effects in agent clustering were produced by the initial conditions and behavioral adaptations that increased the agent capacity to access more resources and the likelihood of gregariousness. The approach presented here could be used to analyze past human colonization events or support long-term conceptual design of future human colonization processes with small social formations into unfamiliar and uninhabited environments.
A Benchmark Test for LLM Persona Agents in a Macroeconomic Simulation
Taewan You | Published Thursday, October 08, 2026This model couples a two-asset heterogeneous-agent New Keynesian macroeconomy with a household layer that can be driven in two ways. One is a conventional calibration. The other is a set of large-language-model persona agents built from real survey households in Korea (NaSTaB), the United States (PSID) and Italy (SHIW). Each persona is given its balance sheet, income and prices, and reports consumption, saving and labour supply. A feasibility layer enforces the budget constraint. A conditional-mean surrogate then turns these decisions into a propensity surface. That surface reaches the macroeconomic block through a single channel, the intertemporal marginal propensity to consume matrix. Because of this, a calibrated “twin” can be aligned with the generative layer exactly, and the two can be compared policy by policy.
Both layers are then scored against the held-out consumption of the same households. The model’s role is to serve as a benchmark: it tests whether generative agents add information beyond the balance sheet, and whether that information matches real behaviour.
The deposit contains:
…
Displaying 10 of 378 results for "Daniel J Singer" clear search