Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 203 results for "Nuno Pinto" clear search
EU language skills
Marco Civico | Published Sunday, July 07, 2024The objective of this agent-based model is to test different language education orientations and their consequences for the EU population in terms of linguistic disenfranchisement, that is, the inability of citizens to understand EU documents and parliamentary discussions should their native language(s) no longer be official. I will focus on the impact of linguistic distance and language learning. Ideally, this model would be a tool to help EU policy makers make informed decisions about language practices and education policies, taking into account their consequences in terms of diversity and linguistic disenfranchisement. The model can be used to force agents to make certain choices in terms of language skills acquisition. The user can then go on to compare different scenarios in which language skills are acquired according to different rationales. The idea is that, by forcing agents to adopt certain language learning strategies, the model user can simulate policies promoting the acquisition of language skills and get an idea of their impact. In this way the model allows not only to sketch various scenarios of the evolution of language skills among EU citizens, but also to estimate the level of disenfranchisement in each of these scenarios.
Netlogo Aquaponic Simulation
Derrick | Published Tuesday, October 06, 2026 | Last modified Wednesday, October 07, 2026This agent-based aquaponics simulation models the biological resilience and complex dynamics of a closed-loop agricultural system. Designed for educational use and agricultural research, the model helps aquaponic designers, farmers, and hobbyists understand systemic dynamics and stress-test species configurations prior to a physical build. The simulation dynamically models the nitrogen cycle by tracking aquatic bio-loads, bacterial filtration, and plant nutrient uptake. Utilizing real-world biological metrics from the Loyola Global Aquatic Excrement Dataset, the model calculates species-specific ammonia excretion rates (toxicity) for various aquatic life, including Trout, Tilapia, and Goldfish. Nitrifying bacteria agents convert this toxicity into usable nitrates, which are then absorbed by specific crop agents—such as Tomatoes, Swiss Chard, or Lettuce—at variable rates. Key features include dynamic stochastic harvesting, measurable agent health, vermaculture and crawdad integration, and reactive biological mitigators like emergency duckweed buffering. The system also introduces chaotic environmental variables, allowing users to test the agricultural setup’s resilience against random shocks like bio-filter pump failures and temperature crashes. This model is released under the GNU General Public License v3.0 (GPL-3.0) to encourage collaborative improvement within the academic and farming communities.
Coupled Housing and Land Markets (CHALMS)
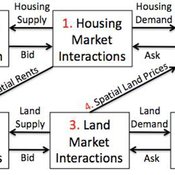
Nicholas Magliocca Virginia Mcconnell Margaret Walls | Published Friday, November 02, 2012 | Last modified Monday, October 27, 2014CHALMS simulates housing and land market interactions between housing consumers, developers, and farmers in a growing ex-urban area.
Risks and Hedonics in Empirical Agent-based land market (RHEA) model
Tatiana Filatova Koen de Koning | Published Monday, April 01, 2019RHEA aims to provide a methodological platform to simulate the aggregated impact of households’ residential location choice and dynamic risk perceptions in response to flooding on urban land markets. It integrates adaptive behaviour into the spatial landscape using behavioural theories and empirical data sources. The platform can be used to assess: how changes in households’ preferences or risk perceptions capitalize in property values, how price dynamics in the housing market affect spatial demographics in hazard-prone urban areas, how structural non-marginal shifts in land markets emerge from the bottom up, and how economic land use systems react to climate change. RHEA allows direct modelling of interactions of many heterogeneous agents in a land market over a heterogeneous spatial landscape. As other ABMs of markets it helps to understand how aggregated patterns and economic indices result from many individual interactions of economic agents.
The model could be used by scientists to explore the impact of climate change and increased flood risk on urban resilience, and the effect of various behavioural assumptions on the choices that people make in response to flood risk. It can be used by policy-makers to explore the aggregated impact of climate adaptation policies aimed at minimizing flood damages and the social costs of flood risk.
Artificial Long House Valley-Black Mesa
Lisa Sattenspiel Amy Warren | Published Thursday, March 19, 2020This model is an extension of the Artificial Long House Valley (ALHV) model developed by the authors (Swedlund et al. 2016; Warren and Sattenspiel 2020). The ALHV model simulates the population dynamics of individuals within the Long House Valley of Arizona from AD 800 to 1350. Individuals are aggregated into households that participate in annual agricultural and demographic cycles. The present version of the model incorporates features of the ALHV model including realistic age-specific fertility and mortality and, in addition, it adds the Black Mesa environment and population, as well as additional methods to allow migration between the two regions.
As is the case for previous versions of the ALHV model as well as the Artificial Anasazi (AA) model from which the ALHV model was derived (Axtell et al. 2002; Janssen 2009), this version makes use of detailed archaeological and paleoenvironmental data from the Long House Valley and the adjacent areas in Arizona. It also uses the same methods as the original AA model to estimate annual maize productivity of various agricultural zones within the Long House Valley. A new environment and associated methods have been developed for Black Mesa. Productivity estimates from both regions are used to determine suitable locations for households and farms during each year of the simulation.
Peer reviewed Viable North Sea (ViNoS): A NetLogo Agent-based Model of German Small-scale Fisheries
Wolfgang Nikolaus Probst Jieun Seo Jürgen Scheffran Carsten Lemmen Sascha Hokamp Verena Mühlberger Serra Örey | Published Thursday, May 25, 2023 | Last modified Tuesday, December 05, 2023Viable North Sea (ViNoS) is an Agent-based Model of the German North Sea Small-scale Fisheries in a Social-Ecological Systems framework focussing on the adaptive behaviour of fishers facing regulatory, economic, and resource changes. Small-scale fisheries are an important part both of the cultural perception of the German North Sea coast and of its fishing industry. These fisheries are typically family-run operations that use smaller boats and traditional fishing methods to catch a variety of bottom-dwelling species, including plaice, sole, and brown shrimp. Fisheries in the North Sea face area competition with other uses of the sea – long practiced ones like shipping, gas exploration and sand extractions, and currently increasing ones like marine protection and offshore wind farming. German authorities have just released a new maritime spatial plan implementing the need for 30% of protection areas demanded by the United Nations High Seas Treaty and aiming at up to 70 GW of offshore wind power generation by 2045. Fisheries in the North Sea also have to adjust to the northward migration of their established resources following the climate heating of the water. And they have to re-evaluate their economic balance by figuring in the foreseeable rise in oil price and the need for re-investing into their aged fleet.
On the liquidity of the illiquid (hard-to-trade) assets
Marcin Czupryna | Published Monday, January 13, 2025This paper investigates the impact of agents' trading decisions on market liquidity and transactional efficiency in markets for illiquid (hard-to-trade) assets. Drawing on a unique order book dataset from the fine wine exchange Liv-ex, we offer novel insights into liquidity dynamics in illiquid markets. Using an agent-based framework, we assess the adequacy of conventional liquidity measures in capturing market liquidity and transactional efficiency. Our main findings reveal that conventional liquidity measures, such as the number of bids, asks, new bids and new asks, may not accurately represent overall transactional efficiency. Instead, volume (measured by the number of trades) and relative spread measures may be more appropriate indicators of liquidity within the context of illiquid markets. Furthermore, our simulations demonstrate that a greater number of traders participating in the market correlates with an increased efficiency in trade execution, while wider trader-set margins may decrease the transactional efficiency. Interestingly, the trading period of the agents appears to have a significant impact on trade execution. This suggests that granting market participants additional time for trading (for example, through the support of automated trading systems) can enhance transactional efficiency within illiquid markets. These insights offer practical implications for market participants and policymakers aiming to optimise market functioning and liquidity.
A data-informed bounded-confidence opinion dynamics model
Bruce Edmonds | Published Wednesday, March 10, 2021The simulation is a variant of the “ToRealSim OD variants - base v2.7” base model, which is based on the standard DW opinion dynamics model (but with the differences that rather than one agent per tick randomly influencing another, all agents randomly influence one other per tick - this seems to make no difference to the outcomes other than to scale simulation time). Influence can be made one-way by turning off the two-way? switch
Various additional variations and sources of noise are possible to test robustness of outcomes to these (compared to DW model).
In this version agent opinions change following the empirical data collected in some experiments (Takács et al 2016).
Such an algorithm leaves no role for the uncertainties in other OD models. [Indeed the data from (Takács et al 2016) indicates that there can be influence even when opinion differences are large - which violates a core assumption of these]. However to allow better comparison with other such models there is a with-un? switch which allows uncertainties to come into play. If this is on, then influence (according to above algorithm) is only calculated if the opinion difference is less than the uncertainty. If an agent is influenced uncertainties are modified in the same way as standard DW models.
HOSS(-5): Human Organizations Simulations Start
José Quintás Alonso | Published Friday, October 09, 2026HOSS(-5) is an exploratory agent-based prototype of a small artificial society, written in Python. Each agent is a “ph” (punto humano, “human point”) that is born, is educated, works, consumes and dies. Its yearly decisions depend on a psychological profile (archetype × character), its economic status and its intentionality. Agents interact indirectly through families, firms in 10 sectors, a labour market with about 200 job categories, and a State that provides public services, employment and a Universal Basic Income, adjusting taxes and UBI each year to seek fiscal balance.
The model simulates a few thousand agents over decades of virtual time and records yearly aggregates (population, GDP, income, Gini index, HDI). A separate analysis script explores the results and fits Gamma distributions to individual incomes, comparing the shape parameter with Gini and HDI.
HOSS does not aim to predict real societies or claim empirical validation. It is a sandbox for comparing scenarios and thinking about the organizational design of society from an engineering perspective. Known limitations: no direct social relations between agents, prices and production follow simple rules rather than supply-demand dynamics, and organizations are black boxes.
…
The Targeted Subsidies Plan Model
Hassan Bashiri | Published Thursday, September 21, 2023The targeted subsidies plan model is based on the economic concept of targeted subsidies.
The targeted subsidies plan model simulates the distribution of subsidies among households in a community over several years. The model assumes that the government allocates a fixed amount of money each year for the purpose of distributing cash subsidies to eligible households. The eligible households are identified by dividing families into 10 groups based on their income, property, and wealth. The subsidy is distributed to the first four groups, with the first group receiving the highest subsidy amount. The model simulates the impact of the subsidy distribution process on the income and property of households in the community over time.
The model simulates a community of 230 households, each with a household income and wealth that follows a power-law distribution. The number of household members is modeled by a normal distribution. The model allocates a fixed amount of money each year for the purpose of distributing cash subsidies among eligible households. The eligible households are identified by dividing families into 10 groups based on their income, property, and wealth. The subsidy is distributed to the first four groups, with the first group receiving the highest subsidy amount.
The model runs for a period of 10 years, with the subsidy distribution process occurring every month. The subsidy received by each household is assumed to be spent, and a small portion may be saved and added to the household’s property. At the end of each year, the grouping of households based on income and assets is redone, and a number of families may be moved from one group to another based on changes in their income and property.
…
Displaying 10 of 203 results for "Nuno Pinto" clear search